Category Archive: Analysis

  1. Money Parables

    Comments Off on Money Parables

    In the past year, Modern Monetary Theory (MMT) has shifted the policy debate in a way that few heterodox schools of economic thought have in recent memory. MMT’s central notion—that nations with their own strong currencies face no inherent financial constraints—has made its way into politics and, notably, the world of finance. The last few months have brought MMT explainers from financial media outlets including Reuters, CNBC, Bloomberg, Barron’s, and Business Insider, as well as from investment analysts at Wall Street firms including Goldman Sachs, Bank of America, Fitch, Standard Chartered and Citigroup.

    Popularizing the shorthand notion that “deficits don’t matter” has been an achievement for those promulgating MMT. Yet one largely unappreciated change brought about by the MMT debates involves a somewhat subtler point: a shift in the implicit story we tell about money.

    The rise of MMT poses a challenge to the mainstream commodity money story. That parable, familiar to anyone who has taken high school economics or read Adam Smith, involves an inefficient barter system that gives way to the more convenient use of some token that represents value, typically a precious metal. If government plays a role in this story, it is only to regulate money after the marketplace births it.

    The MMT parable—known in the literature as chartalism—reverses the commodity money view. For chartalists, money arises through an act of law, namely the levying of a tax which requires citizens to go out and get that which pays taxes; the state comes first and markets are subsequent. As Abba Lerner puts it, money is “a creature of the state.”

    It is tempting to present the conventional commodity money and charlatist views as two poles in a monetary binary, but there is also a third line of thought, related to yet distinct from the chartalist school. This is the credit money tradition, which sees money’s origins in reciprocal obligations between producers. Unlike chartalism, the credit theory presupposes markets of some sort. Unlike the commodity view, credit theory does not require money to initially take some physical form of value. Government typically plays a role in the story that the credit money school tells, but not the foundational one that it does in chartalism.

    Market societies use narratives to justify the social technology called money. How do the essentially worthless slips of paper in my wallet or the digital entries in my bank account give me command over real resources? Answering this question requires, consciously or not, a story that rationalizes money—even if it’s not exactly accurate. Like the Copernican theory of epicycles, a story can function effectively even if it’s not strictly true. But this sort of story can also lead us astray. As debates around money, debt, and the state continue, it is worthwhile to review these three theories of money, each of which has distinct implications for the role of government in the economy and the limits of monetary policy.

    Commodity Money

    The commodity money story begins with Aristotle, who located the birth of money in large-scale foreign trade. Because “the various necessaries of life are not easily carried about,” traders came to conduct exchange in something “intrinsically useful and easily applicable to the purposes of life” such as iron or silver. Later, some authority stamped the metal discs to save the time of weighing them.

    Two millennia later, Adam Smith wrote his own commodity money parable. Here, money arose from the domestic division of labor between the butcher, the brewer, and the baker. The brewer and baker need meat while the butcher has too much of it. Yet because the butcher has enough bread and beer, no exchange takes place. In a society with a division of labor, then, “every prudent man” would set aside “a certain quantity of one commodity or other, such as he imagined few people would be likely to refuse in exchange for the produce of their industry.” This commodity became money.

    Commodity money got its most rigorous treatment from Austrian economist Carl Menger, who in 1892 devised the notion of saleability to explain money’s origins. In Menger’s theory, trial and error teaches producers to exchange their goods for those commodities that are easiest to sell: at any time, they can be exchanged at the smallest possible discount. Compare, for instance, the ease of selling 10 shares of Apple stock in the next 24 hours versus trying to offload some of the examples Menger gives as not-so-saleable goods: “astronomical instruments, anatomical preparations, sanskrit writings, and such hardly marketable articles.”

    For Menger, money emerges as the “most saleable” commodity. It might be grain or iron, given the circumstances: the point is that it is always accepted because others will take it as well. Money emerges “without convention, without legal compulsion, nay, even without any regard to the common interest,” a product of decentralized exchange that serves only to lubricate the wheels of commerce. Incidentally, Marx’s account of money shares certain similarities with Menger’s story, and some contemporary Marxist interpretations follow in this tradition, such as the recent work of Costas Lapavitsas, who cites Menger favorably.

    Chartalism, or State Money

    The chartalist parable preferred by MMT proponents turns the commodity money story on its head. Instead of money arising in exchange and later getting state approval, chartalist money begins with a central authority. The name chartalism originates with the early 20th century German economist Georg Friedrich Knapp. Knapp chose the word “chartal,” rooted in the Latin word for “ticket,” to describe money as merely a token devised by the state. Knapp imagined a hierarchy of money with state-defined money at the top.

    Knapp’s impenetrable system, which required scores of specialized terms, did not take off. Yet Knapp had his admirers—among them John Maynard Keynes, from whose 1930 Treatise on Money MMT gets its name. Keynes saw the state’s role not only in enforcing money contracts, but, crucially, in the right to define what counts as money. “This right is claimed by all modern States and has been so claimed for some four thousand years at least,” Keynes wrote. Once states exercised this right, “Knapp’s chartalism—the doctrine that money is peculiarly a creation of the State—is fully realised.” “Modern” money thus began with the Babylonians.

    Chartalism advanced with the progressive New Deal-era economist Abba Lerner, father of “functional finance.” In the 1990s the so-called neo-chartalists emerged, among them economists L. Randall Wray and Stephanie Kelton. Each has provided something of a parable for the state money viewpoint.

    In his 1998 book Understanding Modern Money, Wray imagines a hypothetical colonial governor who wants her subjects to build her a mansion. After futile efforts at getting the natives to work by offering wages and threatening violence—because they are ignorant of “money, prices, and markets”—she finds that taxation will do the trick. She levies a tax and offers paper money (adorned with her face) in exchange for labor done in her service. The state pays people who work for money so that they will pay taxes back to the state. Eventually the governor gets her house. (Such a process has indeed occurred throughout history, especially as part of the process of European colonialism.)

    Kelton has offered a more politically palatable narrative. To illustrate the notion that the state must spend money before it is taxed back—that money is not something external to the state that it needs to acquire—Kelton offers the analogy of the game of Monopoly. For a game to begin, the “banker” gives everyone money. It would make no sense if the game began with the banker (i.e., the state) demanding payment of taxes so that the state could then spend. The lesson, says Kelton is that “somebody has to spend the currency into the game or the game can’t begin.” This is the role of the state.

    Neither Wray’s parable nor Kelton’s explains the origins of money in a literal sense. In the colonial governor story, the governor must be already familiar with money before it is thought to emerge. Commodity money stories suffer from a similar chicken-egg problem: Smith and Menger each take as given the existence of well-developed domestic markets. But would these markets exist before money was around to enable them? Notably, Aristotle (as well as Marx) saw money’s origins not in a stylized domestic sphere, but in foreign trade. In fact, Aristotle held that it was the introduction of coin that actually spurred retail trade. Smith’s account reverses this causation.

    Credit Money

    The credit money tradition takes as its starting point debts between producers. Though various thinkers in the 18th century prefigured credit theory, it was finally stated in full by the idiosyncratic Scottish economist Henry Macleod in 1889, for whom money is “merely a Right or Title to acquire some satisfaction from some one else, i.e., a Credit.”

    The credit money parable draws its characters directly from Smith’s barter parable. Advancing Macleod’s thesis in the 1910s, economist A. Mitchell Innes imagined a baker and brewer bartering for meat from a butcher who, again, needs neither bread nor beer. Instead of fixing upon some physical item to serve as an exchange token when direct barter fails, the merchants just exchange IOUs. As long as “the community would recognize the obligation of the baker and the brewer to redeem these acknowledgments in bread or beer at the relative values current in the village market,” we have “a good and sufficient currency.” The community’s recognition of the mutual debts may take the form of a state decree that x is the money of account, that is, x is how debts are measured and extinguished.

    The idea that money is best thought of as credit would prove influential. Schumpeter lent substantial support to the credit-first view of money. Post-Keynesian economists from Nicholas Kaldor and Paul Davidson onward operated from a credit-money viewpoint. There is also some overlap between the credit and neo-chartalist approaches. MMT emerged largely from post-Keynesian circles, and neo-chartalists endorse some credit-money notions (Wray is largely responsible for resurrecting Innes).

    The fuzzy boundary between chartalism and credit money is not a recent phenomenon. In the same chapter that Keynes describes “modern” money as state money, he notes that in reality, “the use of bank money is now so dominant that much less confusion will be caused by treating this as typical and the use of other kinds of currency as secondary, than by treating State money as typical and bringing in bank money as a subsequent complication.” That is, credit money—money borne ab initio from the lending of banks—logically precedes state money.

    Why money parables matter

    When we judge monetary parables, exact correspondence to history is not the primary criterion. As Keynes wrote, money’s true origins “are lost in the mists when the ice was melting, and may well stretch back into the paradisaic intervals in human history of the interglacial periods, when the weather was delightful and the mind free to be fertile of new ideas.”

    Money parables serve a purpose beyond historical specificity. They highlight aspects of money that theorists believe are paramount to economic life as we know it. For commodity money theorists, the essential economic fact is that of depersonalized market exchange between strangers. For chartalists, the point is the state’s power of monetary coordination; money does more than grease the gears that power the market. In the third view, credit money, uncertainty and mutual obligation take precedence.

    Any theorist can pull from the depths of economic history some event that proves their narrative is the “right” one. But having the “right” origin story is not the main purpose of a money parable. Money parables identify the key aspects of money as it currently operates and rationalize its social purpose.

    A nice contrast between two money parables can be seen in recent publications by two of the world’s foremost central banks: the U.S. Federal Reserve system and the Bank of England. The New York Fed publishes educational comics explaining the monetary system. One issue, titled “Once Upon A Dime,” is essentially Adam Smith’s parable but with cartoon aliens. By contrast, the BoE’s 2014 publication “Money Creation in the Modern Economy” takes a more modern view: “Whenever a bank makes a loan, it simultaneously creates a matching deposit in the borrower’s bank account, thereby creating new money,” the authors write. Money, the BoE says, is credit.

    As the sociologist of money Geoffrey Ingham writes, monetary systems require “naturalizing” narratives—stories that convince us that money is not just some flimsy social construct, but something solid and necessary. The commodity view has obvious intuitive appeal: paper money has value because it stands in for something weighty and real. It may be less intuitive to see the monetary system as a set of interlocking promises or a government construct.

    In some ways it doesn’t matter which parable holds sway, as long as it “works.” Copernican astronomers could predict the motions of the planets quite accurately using the artificial notion of epicycles; analogously, the modern entrepreneur might build a billion-dollar company under the illusion that each dollar must have some physical thing backing its value.

    But eventually the wrong story can lead to error. Such was the case in the post-crisis years, when the Fed began its quantitative easing program, trading its own newly “printed” dollars for privately held financial assets in order to drive down interest rates on outstanding bonds. Those with a doctrinaire commodity-money view warned that such money creation could only lead to inflation. But as MMT proponents and credit-money theorists predicted—along with conventional economists less rigidly tied to the commodity-money view—quantitative easing did not spark runaway inflation. The recent predictive record of non-mainstream economists is in large part why Wall Street and financial media have given hearing to heterodox monetary ideas.

    Much of the debate over MMT has to do with specific policy proposals, like the jobs guarantee or the suggestion that government not issue bonds. But underlying those specifics is an often unstated dispute over the nature of money and the stories we tell to comprehend it. Wherever one comes down on the validity of MMT’s claims, it would be beneficial if the current fervor around government debt and monetary policy leads to a wider recognition of the various narratives one can tell about money.

    Experience and history show that the commodity view is insufficient to explain all the attributes of the institution of money. The dimensions of money that are downplayed in the textbook Smith-Menger barter narrative—credit and the state—are of central importance in understanding both how modern money likely arose and how it operates now. Economics education at every level ought to include and even privilege those narratives that foreground the role of debt and the state in money’s origins and operation.
  2. Decentralize What?

    Comments Off on Decentralize What?

    The internet’s early proliferation was steeped in cyber-utopian ideals, which predicted that networking technology would usher in an era of free-flowing information and global emancipation from oppression. The circumvention of censorship and gatekeeping, digital public squares, direct democracy, revitalized civic engagement, the “global village”—these were all anticipated characteristics of the internet age, premised on the notion that digital communication would provide the necessary conditions for the world to change. In a dramatic reversal, we now associate the internet era with eroding privacy, widespread surveillance, state censorship, asymmetries of influence, and monopolies of attention—exacerbations of the exact problems it portended to fix.

    The free-flow of information is surprisingly easy to impede (as evidenced by China’s persistent internet censorship and Egypt’s internet shutdown in 2011) and surveil (as is the case with the US’s Room 641A). There is a technical explanation for this: Most traffic is routed through a small number of services that rely on a few key architectural points. Consequently, targeted attacks or outages have a disproportionately widespread effect. The Mirai botnet launched a DDoS attack on the Dyn DNS in 2016 that hindered access to many major sites, including Amazon, GitHub, Slack, Squarespace, and Netflix. Because of how the internet is structured, people who were in the same building couldn’t communicate over Slack—a service that relies on passing messages through a geographically distant server before delivering it to the recipient. These attacks are expected to become more frequent as poorly-secured internet-of-things devices continue to proliferate.

    The same structure that makes these attacks so effective also contributes to a more general brittleness, even in the absence of hostility. Amazon Web Services (AWS), which controls 40% of the cloud market (it’s unclear how much of the internet this actually is, but it’s safe to assume that it’s a large amount), similarly takes out a large set of popular services during its various outages.

    These issues are frequently understood as falling into two categories of centralization: Infrastructural centralization accounts for the fragility that enables DDoS attacks, and political centralization motivates oppositional institutional behavior like mass surveillance and censorship. The two are obviously mutually reinforcing; for example, mass surveillance is made easier with infrastructural centralization.

    If these are problems of centralization, then decentralization looks like a natural remedy. In the context of the internet, decentralization generally refers to peer-to-peer (p2p) technologies, which have recently regained interest in the form of blockchains and federated applications like Mastodon. Reminiscent of cyber-utopianism, this new technological paradigm presages similar social and political change. But what are we decentralizing exactly, and to what ends? There are many parts of the internet that could be decentralized—physical infrastructure, the protocols by which computers communicate, the end-user applications we spend our time on—each yielding different outcomes. Discussions about decentralization and the internet tend to conflate these different possibilities, indicating only a vague, monolithic end rather than recognizing the distinct and various means for achieving particular goals.

    In this post, I consider whether infrastructural decentralization is an effective way to counter existing regimes of political centralization. The cyber-utopian dream failed to account for the exogenous pressures that would shape the internet—rosy narratives of infrastructural decentralization seem to be making a similar misstep.

    Mesh networks

    If we were to conceive of an alternative to the centralized internet, we might start by decentralizing the topology and ownership of its physical infrastructure. As it stands, communication over the internet is mediated by relatively few ISPs over a tree-like structure. Points along the trunk of this tree, where many branches come together, can be easily monitored to surveil large amounts of traffic. An alternative to this structure, mesh networks focus instead on direct connections between devices, such that the network looks more like a fishing net and less like a tree. Communication on a mesh network is not necessarily mediated by an ISP; information can theoretically pass through anyone participating in the network. Rather than having just a few exit points for traffic, a country might have hundreds or thousands of them, all operated by different parties. Accordingly, closing the country off from the internet becomes much more complicated, as there are virtually no single failure points that can collapse in inclement weather, or be shut down, monitored, or filtered by a hostile state.

    Mesh networks are praised for their resiliency to such failures, their capacity to generate alternative models of internet infrastructure ownership and stewardship, and the challenge they pose to the commodification of digital communication. With such “community networks,” access to the internet is no longer contingent on the business interests of a private ISP, but rather on people’s communication needs. When neighborhoods are subject to “digital redlining” or overlooked because of low density, they can deploy local mesh networks and form an intranet among members of those communities. Active community network projects in the US include the Detroit Community Technology Project, NYC Mesh, and Red Hook Wifi.

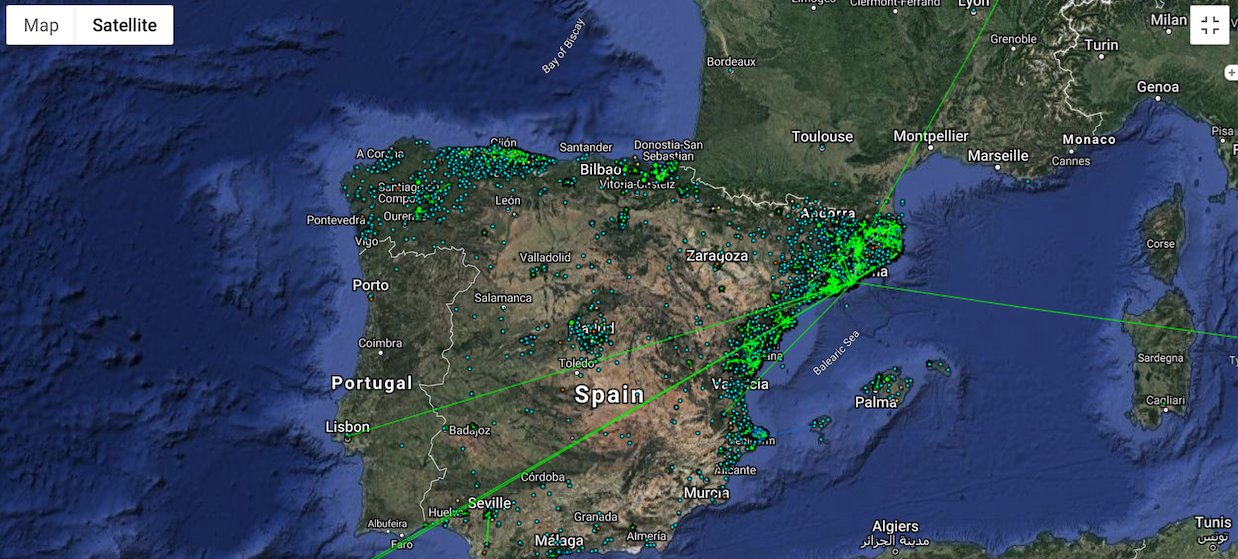
    Community networks outside the US are more common and mature. guifi is the largest community network in the world, composed of some 35,000 nodes that cover most of Catalonia and large parts of Valencia and Asturias. As of 2015, the network required about €7.3 in capital expenditure and costs about €3 million per year. The throughput can vary quite a bit—in 2015, one analysis found the mean throughput to be 17.4Mbps to the internet gateway and 6.2Mbps through it. Compared to other ISPs operating in the area, a study from the same year found the network to rank first in median latency, but the network has been transitioning to fiber infrastructure, which has improved speeds. The service is priced at cost, leading to considerably lower prices: in 2016, a guifi gigabit fiber connection cost around \$20–\$37 a month. In comparison, Xfinity’s gigabit service costs $105 a month today. guifi seems successful in expanding affordable and high-speed digital connectivity.

    guifi nodes, as of 05/23/2019. See: https://guifi.net/maps

    This setup doesn’t provide complete autonomy, however. An ISP is still required to communicate to the broader internet beyond the mesh network. This is a limitation of scale: if mesh networks grow in popularity, ISPs will become less and less necessary as various local mesh networks can merge into larger aggregate networks.

    That the architecture of a mesh network consists of physically decentralized components does not mean that it’s managed in a decentralized way, nor does it imply particular values guiding the decision-making or application of the network. Mesh networks may be deployed exclusively for their fault tolerance—a quality that appeals to a range of political actors, including the military. And they don’t necessarily need to be priced at cost or made accessible—it’s easy to conceive of an ISP that operates a mesh network, owning a majority if not all of its nodes (for example, this startup in Philadelphia which requires that users watch ads to access the network). Community networks such as guifi take a decentralized technical architecture and extend that notion of decentralization to its social and political meanings—ensuring access, participation, and ownership are central to the network’s development.

    Networking protocols

    Networking protocols define how computers find and talk to one another, and centralization at the network level can contribute to the effectiveness of the DDoS attacks described above. In the present client-server paradigm, the vast majority of computers (clients) are looking for and talking to a much smaller subset of computers (servers). For example, 2.3 billion people access Facebook’s servers every month. The content and data that those people are interested in are more or less exclusively located on Facebook’s servers. If an interested attacker can wrangle enough bandwidth, they could attack some key part of Facebook’s infrastructure to disrupt access for many of those 2.3 billion people.

    p2p networking protocols, on the other hand, seek to distribute data (and the traffic that accesses it) across the very computers that are looking to access it. This tit-for-tat structure is key to p2p networking protocols and is part of the more horizontal structures that these protocols are built around. Using and contributing to the network are essentially the same act. This sharing of network load can lessen the impact of DDoS attacks—because there is no longer a piece of key infrastructure that can be targeted, every computer becomes equally (un)important.

    Though p2p protocols aspire to have a fully horizontal network topology in which peers are interchangeable, there is a spectrum of hierarchy throughout their designs. Hierarchization can have important effects beyond protocol operation—Napster, for instance, had a high degree of centralization, with an index server coordinating peer connection. The index server was managed by the company and thus, the courts ruled, made them liable for the file-sharing that occurred on the network. At the opposite end, protocols like Gnutella are completely non-hierarchical and rely on “flooding,” in which peers blast all other peers with requests, which is very inefficient and unreliable. Protocols like Kademlia are hierarchically flat like Gnutella but not marred by its problems, with good guarantees on efficiency and reliability. Kademlia’s simple design demonstrates that the tradeoff implied by hierarchical networks—between resilience and efficiency—isn’t necessary.

    p2p networking protocols are often designed to work on existing internet infrastructure, forming a “virtual” or “overlay” network on top of the underlying physical network. Even if the actual packets between computers are routed via conventional ISP infrastructure, they communicate as if they were directly connected. This reliance on the topology of the physical network exposes overlay networks to the same fragility their underlying physical network is exposed to. For example, in the current tree-like structure of internet infrastructure, traffic on an overlay network may still enter and exit a country at only a few points, and those points could be shut off to sever the network. In the case of file-sharing, this is what enables ISPs to prosecute file-sharers.

    Mesh networking would of course resolve these ISP issues. Overlay networks are generally portable to mesh networks, so the two would be straightforward to combine in practice. p2p networking protocols complement mesh networks by providing more flexible and efficient routing. They also support decentralized applications like distributed storage, which enables faster content delivery, file-sharing, and better censorship resistance.

    Interestingly, p2p networking is about as old as computer networking in general. ARPANET, the 1960s precursor to the internet, was originally designed as a p2p network. Over time the p2p aspect of the internet faded in favor of the client-server relationship, until the late 90’s when file-sharing applications like Napster, Gnutella, Limewire, and Kazaa re-introduced the concept to broader audiences.

    p2p networking protocols decentralize the responsibility of storage and routing on a network. Yet there aren’t strong guarantees that this decentralization will persist or proliferate—a centralized social networking application could conceivably be built on top of a p2p architecture. While these protocols may provide more reliability than Facebook’s current infrastructure, they don’t preclude the existence of something with as much influence and power as Facebook. Just as the unprecedented consolidation of wealth and political power by large internet services reflects exogenous system characteristics as much or more than their underlying technical architecture, a p2p social network application could, in practice, lead to a similar centralization of power and influence.

    More immediately troubling is that there is an entire class of attack known as Sybil attacks which fundamentally undermine the security of p2p networks. Sybil attacks provide a way for covert centralization to emerge, where a swarm of seemingly distinct peers are actually controlled by a single party. With a large enough set of Sybil peers, that party can effectively shut off parts of the network, serve malicious files, or surveil traffic. In practice, there are several techniques proposed to lessen the effect of such attacks, but there is no way to eliminate them entirely. In p2p networking protocols, as with mesh networking, the realized infrastructural decentralization is contingent on factors exogenous to the protocol.

    Blockchains

    Blockchain is a relative newcomer to the p2p space and is probably the most well-known. The technology itself focuses on achieving consensus across a set of computers, ultimately taking the form of an append-only ledger. But what other forms of decentralization does this achieve?

    On its own, not much. This decentralized consensus mechanism is one component of a much broader system, similar to how mesh networks and p2p networking protocols address problems in different layers of networking infrastructure. A decentralized consensus mechanism is on its own not incompatible with other centralizing tendencies. One key assumption for the security of blockchains is that the pool of miners—participants whose responsibility it is to validate transactions (additions to the ledger)—be as distributed as possible. Over time, however, these miners have become rather concentrated. Consider Bitcoin: at least 70% of mining is in China, largely owing to factors exogenous to the protocol like access to mining hardware and cheap electricity. In blockchain, acknowledgement of this fact leads to the reintroduction of other forms of decentralization.

    At the blockchain application level, “decentralization” is typically conflated with “markets,” which emphasize token economies, mechanism design, and economic incentives. For example, curation markets (e.g. FOAM), prediction markets (e.g. Augur and Gnosis), and data markets (e.g. Ocean Protocol). For Ethereum itself, market and market-inspired structures underlie much of the design and thinking around the protocol. Yet a market structure does not necessarily follow from the underlying distributed consensus mechanism. This tendency towards market mechanisms is likely a bias owing to the technology’s financial genesis: blockchain, via Bitcoin, was introduced as a currency and received as a way to abolish central banks. Many early adopters of blockchain were from finance, including Consensys (perhaps one of the most prominent blockchain companies) and Ethereum co-founder Joseph Lubin, who was VP of Technology for Goldman Sachs’ Private Wealth Management division. Of course, the ongoing speculative nature of cryptocurrencies contributes to this image as well. “Cryptoeconomics”, the primary design practice around blockchain protocol design, is concerned with structuring interactions around idealized economic incentives such that the importance of trust is minimized, often to the point where these protocols are described as “trustless.” To make these protocols viable under such a framework, they usually are built around tokens—quantifiable, exchangeable, and (usually) fungible units. Resulting inequities in accumulation, or token wealth, become part-and-parcel of the protocol. This doesn’t seem particularly decentralized: inequities in wealth are tantamount to the consolidation of influence. But that may not be the kind of decentralization these applications are concerned with.

    Another way this financial legacy emerges is through the primary contender to replace proof-of-work, the current key component behind the distributed consensus mechanism. The proposed replacement is proof-of-stake which takes on a framing of investment. Rather than devote intensive computational power to validate transactions, one “stakes” some of their wealth and is compensated with a return based on the staked amount. While there is some protection against leveraging wealth to influence the network—if you validate a fraudulent transaction, you lose your stake—this mechanism is a feedback loop where wealth begets wealth, exacerbated by the fact that larger stakes are more likely to be selected to validate (some protocols let smaller stakers pool together so they can compete). This can translate into centralization endogenous to the network, or exogenous centralization that bears upon the network in different ways, such as bribes to influence the governance of the protocol.

    Ongoing conversations around governance in blockchain point to another layer in the blockchain stack, where what is meant by decentralization is unclear. Questions of governance in blockchain amount to a reckoning that the blockchain is surrounded by not-so-decentralized structures and processes. In particular, the governance conversation focuses on decision-making around protocols—i.e. the design of blockchain systems. If the protocol needs to be changed, who has what say in that decision? The conversation broadly cleaves into two camps: “off-chain” governance, which privileges a clergy of protocol developers and miners (i.e. informal power with limited accountability), and “on-chain” governance, which institutes some formal mechanism for input from more or less everyone using the platform. On-chain governance subdivides into roughly two further distinctions: one-person-one-vote and one-token-one-vote. One-person-one-vote is complicated by Sybil attacks: if it’s cheap to create new identities on a blockchain, then a person can create many identities and vote multiple times. One-token-one-vote, on the other hand, is equivalent to instituting a plutocracy. The more tokens (wealth) you have, the larger your influence. A plutocratic regime is the de facto standard for on-chain governance; it is taken as the lesser of the two evils, a formal endorsement equating wealth with trustworthiness. Because plutocracy looks like the only alternative, off-chain governance—the clergy option—is frequently advocated.

    The Sybil attack is the most persistent problem in p2p networking. It constantly plagues the design of p2p protocols, because if an attacker can flood the network with bots or spam they can disrupt or manipulate it. The paper that introduced the attack concluded that there is no guaranteed prevention that doesn’t involve a trusted central authority that assigns or verifies identities. Relying on a centralized institution is exactly what these systems don’t want to do! And so the plutocratic option, in one light, looks like the most decentralized option available.

    But this conclusion takes for granted that having a voter verification body is more centralized than a plutocracy and a clergy class, and the appropriateness of that conclusion largely depends again on what one thinks decentralization is for. Is it just to ruthlessly eliminate institutions? Or is it to, as much as possible, set up a system of equitable decision-making? If the goal is the latter, it seems that under all circumstances a plutocratic system and a clergy class are going to be unequal, whereas one-person-one-vote, even with the introduction of a mediating authority, has a greater potential of being more equal.

    Conclusion

    The conversation around decentralization and internet technologies too frequently takes for granted unstated goals around authority, ownership, and governance, conflating infrastructural decentralization with the realization of these less technical goals. This can be read as a failure to account for the political environment in which a new technical infrastructure will be deployed. The development and deployment of these new technologies must be considered against explicit goals and evaluated against the existing contexts that will influence its development.

    Thanks to Arthur Röing Baer, Sarah Friend, and Maksym Rokmaniko for their feedback on the piece.

  3. Student Debt & Racial Wealth Inequality

    Comments Off on Student Debt & Racial Wealth Inequality

    In my new working paper, I argue against the idea that student debt forgiveness is a regressive policy. In particular, I argue against claims that the student debt forgiveness plans proposed by 2020 Democratic Presidential candidates Elizabeth Warren and Bernie Sanders amount to handouts to well-off white people. (To download the output data behind the charts in the paper, click here.)

    My research contrasts with the received wisdom on the impact of student debt cancellation on racial wealth inequality, and more generally with the conventional wisdom on the distributional impact of student debt cancellation along dimensions other than race. The idea that student debt cancellation is a giveaway to the rich just isn’t sustainable in the data.

    In fact, my results show that the set of households with student debt is a relatively disadvantaged, rather than a relatively advantaged, subset of the population. In combination with prior work, we can say that the distribution of student debt has been shifting down the distribution of income and wealth: those with lower economic status account for a larger and larger share of outstanding student debt over time, because 1) they have to take on more of it than they once did in order to enter the labor force (i.e., more than zero), and because 2) they have more trouble paying it off, as wages have stagnated in the labor market and repayment periods have lengthened. Whereas once student debt was a marker of relative privilege in the labor market—confined to high-status graduate degree holders—it is increasingly a mark of relative lack of privilege.

    My new working paper focuses on the implications of student debt cancellation for racial wealth inequality. The more debt cancellation there is, the more racial wealth inequality is reduced—at least among the plans that have actually been proposed. It might be possible to construct a student debt cancellation plan that worsened racial wealth inequality—by explicitly or implicitly barring black people from it, for example—but such a plan is not actually on the table.

    In contrast with the rhetoric of regressivity and college being “worth it” because of the lifetime college earnings premium, student debt matters less to the wealth portfolios of richer people. The fact is that high-wealth households get to be where they are not because they took on student debt in order to obtain valuable degrees, but because they didn’t take on student debt to obtain those degrees and high social and economic status—or, if they did, that debt has already been paid off. This is the sense in which Matt Bruenig’s analysis of the distributional impact of student debt cancellation is flawed: the set of households with outstanding student debt is not an arbitrary delineation of households, relative to those households who didn’t go to college or who paid off their debt. In fact, the set of people with outstanding student debt is a good approximation of the set of people most harmed by the policy failure of student loan debt: the vast expansion of student borrowing against a credentializing labor market with stagnant wages and a “last in, first out” hiring dynamic that particularly disadvantages people of color. This, fundamentally, is why student debt cancellation is racially egalitarian.

    Confronting this policy failure—and the shift it represents in moving the cost of job training from employers, institutions, and states onto individuals—requires interrogating the “skills gap” ideology that motivated the formation and subsequent expansion of the federal student loan program. Starting in the late 1960s, the federal government began to adopt the thinking behind the economic concept of “human capital” into public policy: that the role of education, especially higher education, is for individuals to “invest” in their future earning power by obtaining skills in their youth that raise their value to employers over the course of their careers. According to such thinking, the role of public policy in higher education is, if anything, to complete the capital market: to ensure that individuals can finance their upfront investment in human capital, at a time in their lives when they lack the ability to collateralize such an investment. Thus, the government has a role, albeit a limited one: to guarantee private loans (and much more recently, to act as the direct lender), through which individual students can obtain access to the skill-formation that is the core function of higher education.

    It’s important to recognize that this conception of what higher education policy aims to accomplish post-dates the expansion of public higher education that occurred following the passage of the GI Bill, as well as state-led efforts to build out university systems, such as the California Master Plan of the early 1960s. Those policies radically expanded access to Higher Education, and in doing so, they opened it up to a student population that looked very different from state tax bases. This dynamic of racial division came to a head in the public mind with the campus protests for civil rights and against the Vietnam War that characterized the late 1960s.

    As a result of that, the expansion of institutional support for higher education out of public budgets appeared to have introduced societal dislocation and conflict onto campuses, along with the influx of new students. Shifting the focus from supporting institutions to supporting individual students, through student debt, and shifting the policy aim from providing a public good to completing the capital market for investment in needed labor market skills, thus had an attraction to federal policy-makers, as evidenced by the Rivlin report of 1969 and the subsequent reauthorization of the Higher Education Act in 1972, which created Pell Grants and Stafford Loans.

    More recently, economists have stressed that wage stagnation and labor market inequality are caused by a “skills gap”—that workers lack the skills necessary for today’s jobs. The existence and supposed growth of the college wage premium, the gap between average labor market earnings of high school graduates and college graduates, has been interpreted as evidence of this skills gap. Thus, the policy solution is to expand the federal student loan program so that more students can have access to increased educational attainment. The availability of federal loans has operated in tandem with shrinking state support for higher education institutions, as policy-makers have used the college wage premium to justify shifting those costs onto students in the form of higher tuition. Supposedly, the increase in debt necessary to finance that tuition would ultimately be sustainable because the degrees obtained would pay for themselves by causing students’ earnings in the labor market to increase.

    The final piece of the policy and economic background for the student debt crisis and its sharp racial dimension is labor market credentialization and underlying racial wealth inequality, as well as racial segregation in higher education institutions. When the costs of higher education were individualized, those with more family wealth in their backgrounds were better able to shoulder them, and that meant white people. Moreover, labor market discrimination means that black students have to obtain more degrees, and go into more debt, to obtain the same jobs with the same salaries that white people can obtain with fewer degrees and less debt. Finally, white students have access to institutions with larger sources of external support, so racial wealth gaps are essentially replicated at the institutional level. In the worst case, budget cuts to black- and Hispanic-serving institutions have pushed minority students into the predatory for-profit sector, or induced such institutions to become more predatory on their own student bodies themselves.

    The idea that higher education would equalize outcomes by race, regardless of family background, turned out to be a myth: the disposition of policy to de-fund institutions and increase tuition and debt operated against that racially inegalitarian background to widen racial wealth disparities through the “new” instrument of student debt, just as the expansion of housing credit to non-traditional borrowers in the 1990s and 2000s was presumed to be racially egalitarian, but in fact widened racial wealth gaps when the housing bubble burst. In the case of student debt, the bubble isn’t going to burst in the same spectacular fashion that it did in housing because the debt is unsecured, so a debt deflation scenario following a firesale cannot take place. Instead, there is a long, slow diminution in the value of the degrees the student debt financed, in the form of labor market credentialization that worsens the earnings distribution conditional on any one degree and drives people to therefore seek more of them, and take on more student debt to do so, without ever being able to pay it off.

    Worsening student debt repayment schedules for sequential cohorts bespeaks this policy failure, and it is why student debt cancellation is on the table as a policy solution at all. In fact, it is already implied by existing Income-Based Repayment programs, which cap payments as a percentage of current income and so push repayment schedules into the indefinite future. This is de facto debt cancellation through the back door, since it reduces the present value of debt repayments, and since IBR programs come with cancellation provisions following a maximum number of years in repayment (10, 20, or 25, depending on the program), there is already a great deal of cancellation baked into the system. The worse the labor market performs, the larger the implied cancellation. It should be emphasized here that the expansion of student debt and, by that means, higher education attainment, was supposed to be the mechanism by which the labor market would be made to work better, and earnings to grow for better-educated workers.

    Summing up, the racial inequality dimension of the student debt crisis requires us to question whether the skills gap and human capital ideology that motivates recent and current higher education and student debt policy is correct—both as a matter of social science and with regards to its ability to achieve its normative policy aims. If one such aim is to mitigate wealth disparities by race, the current system is failing dramatically. Cancellation would rectify the disparities in racial wealth that the expansion of student debt has caused.

    To get all future Phenomenal World posts directly in your inbox, sign up here.

  4. The Politics of Machine Learning, pt. II

    Comments Off on The Politics of Machine Learning, pt. II

    For the first part of this article, click here.

    Common differentiation

    The uses of algorithms discussed in the first part of this article vary widely: from hiring decisions to bail assignment, from political campaigns to military intelligence.

    Across all these applications of machine learning methods, there is a common thread: Data on individuals is used to treat different individuals differently. In the past, broadly speaking, such commercial and government activities used to treat everyone in a given population more or less similarly—the same advertisements, the same prices, the same political slogans. More and more, everyone gets personalized advertisements, personalized prices, and personalized political messages. New inequalities are created and new fragmentations of discourse are introduced.

    Is that a problem? Well, it depends. I will discuss two types of concerns. The first type, relevant in particular to news and political messaging, is that the differentiation of messages is by itself a source of problems. Often discussed under the header of (filter) bubbles and political polarization, this concern doesn’t require any “ordering” of political messages, in the sense that some messages are inherently better for the recipient than others—the question is whether it is bad that different people are coming to live in incommensurably different (political) worlds.

    The second type of concern is about fairness, discrimination, or equality. This type of concern requires that some treatments are better than others. In the examples above, for instance, lower prices, a greater chance of being hired, and a lower chance of being incarcerated are usually deemed preferable. The question is whether it is unfair that different people are being charged different prices, or have a different chance of being sent to jail while on trial.

    Filters and bubbles

    The amount of news items or pieces of political information that we could get to read is, for all practical purposes, infinite. Any method of delivering news or information is therefore by necessity selective. And any selection is necessarily ideological: Whose death matters enough to be reported? What social or environmental issues are brought to our attention? Which corruption scandals deserve discussion?

    Selectivity is nothing new. Any traditional way of delivering news or political messages is selective. What is new with algorithmic selection is that the results are highly individually customized. Much of the customization is performed by search engines and social networks—platforms that aim to maximize revenue from ad clicks. Customization is also done by political parties aiming to maximize effective vote shares.

    Filter logics

    Various logics drive the customization of our news feeds. Content is presented to internet users in the form of ordered lists, and since, in practice, we only ever see the top of these lists, the ordering constitutes a selection of what we get to see.

    The simplest way of organizing these lists is by time of posting, with the most recent posts at the top. But on the major social networks, the posts you’re shown are restricted to those posted by your connections, or by the pages you follow.

    Search engines rank pages by potential relevance to your search. The most famous method of doing so—popularized by Google—is to create page ranks, where pages receive a higher ranking if other webpages link to them, and greater weight is given to links coming from pages that have high rank themselves.

    The ordering on more recent implementations of social networks and search engines tends to be considerably more complex. A great number of variables specific to the reader, the poster, and the content itself are used to predict the likelihood of engagement, and posts are ordered and selected accordingly.

    Bubbles and poles

    These various filtering logics contribute to an individually specific version of the world, constructed via selection. To the extent that your connections and the pages you follow have a similar worldview to you, this results in self-confirming visions of the world.

    Filtering by predicted engagement results in a self-confirming bubble: Any time you click on a link, share or like a post, that information is recorded, and you are then more likely to see similar posts in the future—and less likely to see different posts.

    It is often argued that filter bubbles contribute to political polarization and the breakdown of communication across political camps. There is merit to the observation that the news content seen by different people is drifting apart because of these selection effects. But skepticism is due regarding the argument that this is a prime explanatory factor of recent political developments. Older voters, less likely to receive their news and political information online, are more polarized in their political opinions than youth. And the bad old cable news channels, which do not rely on any individual customization, might have at least as much to contribute to polarized (and bigoted) worldviews as search engines and digital social networks.

    Disenchantment

    Let’s move on from the filtering of online news to the targeting of political campaigns. What are the consequences of such targeting? First, only a small subset of the electorate is actively targeted by campaigns. This is already true traditionally, due to the intricacies of electoral systems such as the one in the US. Disproportionate consideration has long been given to swing states and swing districts, where majorities are narrow. Data-driven targeted campaigning, however, massively compounds these effects of the electoral system. To be a valuable target of political resources, one must not only live in a marginal electoral district, but most also be predicted to be on the margin of voting for one party (candidate) or another, or on the margin of voting or not voting. Additionally, those who are targeted receive individually customized messages, rather than partaking in a common narrative.

    It seems certainly plausible that this individualization of political messages contributes to a general disenchantment with electoral democracy. Many voters are ignored because they are irrelevant for winning the election. And those voters who are not ignored might perceive that they are fed whatever they want to hear, by a data driven machinery designed to maximize votes, and that their neighbors might be fed different messages as seen fit by this machinery. Such voters might be forgiven for questioning the authenticity and trustworthiness of the messages they receive. (Interestingly, a conscious choice was made by the Bernie Sanders campaign to forgo the use tailored messaging, sticking instead to the same talking points and arguments for everyone. Consistency helped the campaign’s arguments seem more credible and authentic.)

    Targeting of this kind, then, might maximize votes individually and in the short run, but could backfire in the aggregate and in the long run; if not for the campaigners themselves, then at least for electoral democracy at large.

    Fairness and equality

    Thus far, I have discussed concerns about targeting, driven by machine learning, in the arena of news and politics. Concerns in this arena are primarily not about unfair differentiation between individuals, but about the fragmentation of political discourse.

    Let us now move on to concerns in the arena of the economy and the penal system, which focus on questions of fairness and justice in the differentiation between individuals.

    Transparency

    In Kafka’s novel The Trial, the protagonist Josef K. is arrested by unidentified agents from an unspecified agency for an unspecified crime. He never finds out what he is accused of, nor when his trial is taking place, but he ultimately accepts his execution.

    Machine learning algorithms are similar to the hidden bureaucracy of the The Trial. In many cases they are like a black box, with no human knowing how they came to their predictions or decisions. Suppose your CV is automatically rejected when applying for a job, or you are denied insurance, or you are jailed while awaiting trial. Often these decisions are made by a machine, based on past data. In practice you have no way of knowing which data about you went into the decision, and how these data influenced the decision.

    To remedy this situation and introduce at least some degree of “due process” would require algorithmic transparency. For important decisions, one should have a right to know what information was used to make these decisions, and how the decisions depend on that information. There should also be a right to contest inaccurate information.

    The unfairness of targeting

    Transparency is a fairly minimal requirement, stating a right to know how unequal treatment came about. Inequalities in treatment themselves might be considered unfair, however, even when they are transparently generated.

    Algorithms can be criticized on the basis of various notions of fairness. First, prediction algorithms might systematically reproduce pre-existing biases against certain groups. Algorithms that assess job-candidates, for instance, might discriminate against women, since in the past women were less likely to be promoted for that job.

    Second, it is considered discriminatory to use certain variables—like race and gender—in the decision process at all. A judge, for instance, should not be able to treat a Black defendant differently from a white defendant with a similar biography and criminal history.

    Third, even if certain variables such as ethnicity or gender are excluded from prediction, algorithms might still treat the corresponding groups systematically differently. With enough other data, it is fairly easy for an algorithm to “guess” someone’s ethnicity or gender, and to implicitly base decisions on this guess.

    Fourth and finally, it might be argued that fairness demands the same treatment of everybody not only between groups, but also within groups. Why should some people go to jail and others not, based on crimes they haven’t yet committed? And why should some people pay more than others for goods they purchase, just because they need them more?

    These four criticisms are based on increasingly stronger notions of fairness. The development of technology pushes us to question each notion of fairness and move to the next: Even if algorithms get predictions right, they will discriminate; even if explicit discrimination is prohibited, algorithms are able to discriminate implicitly; even if equality across groups is enforced, within-group inequality might persist.

    Widening the frame

    These notions of fairness take a rather narrow frame: Is it justifiable that different people in a particular situation are treated differently? It is advisable to take a step back and instead ask a bigger question: What impact does differentiated treatment have on social inequality more broadly, and how do we evaluate this impact?

    What “big data” and “machine learning” do to economic and social inequality depends upon how new inequalities in treatment align with pre-existing inequalities. If the new algorithms are less likely to hire women, more likely to send black defendants to jail, or to charge poor people higher prices, then they amplify pre-existing inequality. But we could conceive of the opposite happening as well—if unequal treatment were negatively correlated with pre-existing inequalities. It might happen for instance that targeted prices will be lower for poorer individuals, because their ability to pay for various goods is smaller. It is hard to say which way this will play out, and the answer will be different across settings. It is all the more important, then, to stay vigilant and to observe how newly generated inequalities in treatment correlate with old inequalities, and how they therefore impact overall social inequality.

    Equality of opportunity?

    Returning to questions of fairness, how should we think about whether unequal treatment by algorithms (or by society more generally) is unfair? Many people subscribe to some version of the idea of “equality of opportunity,” which suggests that inequality brought about by circumstances that one has no control over is unfair. For instance, children of poor parents should have the same chances as children of rich parents. (As documented by recent research, that is very much not the case. In particular in the US, children of richer parents tend to have much higher incomes themselves, relative to children of poorer parents.)

    But would the absence of such strong intergenerational income inequality qualify as “equality of opportunity?” Should we not also take into account other factors already determined at the time of our birth? How are gender and race incorporated into this framework? Or geography? What about our parents’ education? We can continue building on this list, with each additional factor allowing us to predict a larger fraction of lifetime inequality. As we add more factors, equality of opportunity becomes an increasingly demanding concept.

    Machines pushing our normative boundaries

    Which brings us back to machine learning. If we take seriously the notion that we should not be held responsible for circumstances determined at the time of our birth, then we should consider any predictable inequalities of life outcomes to be violations of fairness. With the accumulation of data and new prediction methods, more and more becomes predictable.

    But when everything becomes predictable, does it even make sense to use prediction to draw a line between “opportunity” on the one hand and “effort” or “deservingness” on the other? We are pushed by technology to question altogether this distinction, as well as notions of fairness restricted to equality across isolated dimensions (such as gender or parental income). We are pushed instead to confront the rising inequalities of outcomes in our society, no matter where they are coming from.

    A utopia of learning machines

    We have discussed some problems that might arise from targeting using machine learning, and from the emergence new inequalities. But is there a chance to leverage targeting and prediction for socially desirable ends?

    Humans are different in innumerable ways—in our tastes and abilities, in our childhood experiences and our biological makeup, and so on. Treating everyone the same in a formal sense does not lead to equal possibilities in life. This is nicely summarized by a cartoon in which a monkey, a donkey and a whale are challenged to climb a tree. To take another obvious real-world example, administering the same medical treatments to everyone would not lead to particularly good health outcomes. Medical treatments need to be targeted to compensate for ailments that have been diagnosed.

    Assume now that we desire to achieve equality along some dimension—let’s call this dimension “possibilities in life.” To maximize and equalize everyone’s possibilities in life, a utopian social policy might leverage machine learning based prediction to provide everyone with the public goods they need, whether in education, medicine, housing, monetary transfers, transport infrastructure, or some other area. Such a policy might achieve more in terms of equalizing possibilities in life than a one-size-fits all policy, forcing everybody to climb up the tree.

    Side remark against the abuse of genetic research

    This line of reasoning, incidentally, also shows the meaninglessness of the type of genetic research often cited by the biologistic right (think of the “Bell Curve”). The classic version of such research uses twin studies to come up with factoids such as “$x$% of IQ is genetically determined.” The more modern variant of such arguments uses sequenced gene data and machine learning methods to predict individual life outcomes.

    Consider, as an example, eyesight. A twin study might plausibly find that genetically identical twins separated at birth have nearly identical eyesight. One might thus conclude that 99% of variation in eyesight is genetic. Now consider a hypothetical government agency distributing free eyeglasses (cheaply procured) of the right strength to everyone who needs them. The end result might be an improvement for everyone and complete equalization of (effective) eyesight. The point of the example is that the share of some outcome that is predictable from genes always depends on social institutions and political choices. The mechanisms that translate biological makeup or other individual conditions to socially relevant outcomes is always mediated by social institutions. Genetic predictability therefore tells us nothing about the scope for political action.

    The same argument holds not just for twin studies, but also for predictability using sequenced gene data. The use of chopsticks, for instance, is highly predictable using sequenced genes. It would of course be ridiculous to conclude that chopstick use is genetically determined and unalterable by social institutions.

    Who owns the data

    To recap, a possible utopian use of machine learning and targeting is to use these methods to compensate for pre-existing inequalities and to provide everyone with the goods they need to maximize their possibilities in life. This contrasts sharply with targeting to maximize profits or votes.

    A third option, beyond the use and ownership of big data by private corporations, or by hypothetical benevolent policymakers, would be to pose the question of property rights in data. As it stands now, none of us have any control or ownership or even knowledge about the data describing us, data that are accumulated constantly.

    There is nothing natural or unavoidable about this situation. One might well conceive of a legal and technological framework where everybody retains ownership of any data that are specific to themselves. In such a framework, data about us might be stored on some secure third party platform, while remaining under our control. We might then decide on a case-by-case basis whether to pass on data about us to anyone requesting them—if we deem so to be beneficial for ourselves. This would require a legal framework where we retain sole rights over our data, but can “rent” them out, similar to the framework for wage labor. Our labor cannot be sold between other parties, but we can decide to work for an employer, while retaining the right to quit at any time. Contrast this with the current regime for data ownership, where we don’t have any possibility whatsoever to “quit.”

    While it is not obvious that such a hypothetical framework would solve all problems and inequalities entailed by machine learning and targeting, it would certainly yield very different outcomes. It would be a worthwhile exercise to spell out the pre-conditions and possible consequence of such an alternative regime.

  5. The Politics of Machine Learning, pt. I

    Comments Off on The Politics of Machine Learning, pt. I

    The terminology would not be out of place in a science fiction novel: “Machine Learning” and “Artificial Intelligence”; “Deep Learning” and “Neural Nets”—Silicon Valley capitalists are pouring vast amounts of money into technologies going by these names. Universities are outpacing each other to create new departments and programs for “Data Science.” College students are rushing into any course with “Machine Learning” in its title. Corporations, political parties, and intelligence agencies are anxious to maintain an edge in the use of these technologies.

    Nothing new under the sun?

    Statisticians might be forgiven for thinking that this hype simply reflects the success of the marketing speak of Silicon Valley entrepreneurs vying for venture capital. All these fancy new terms are just describing something statisticians have been doing for at least two centuries. The vast majority of machine learning methods deal with what is now called “supervised learning,” and is traditionally called “prediction.” Statistical prediction methods were introduced to astronomy and the physical sciences in the early 1800s; somewhat later the social sciences followed suit.

    Prediction works like this: Suppose you have a dataset with a bunch of variables, called covariates (or features, or predictors), and an outcome variable (or label) of interest. The goal of the game is to come up with a good guess (prediction) of what the outcome will be for new observations, based only on the covariates for those new observations. For instance, you might try to predict which party someone is going to vote for in an election, based on your knowledge of their demographics, address, income, etc., after having analyzed a dataset including both these variables and historical voting behavior for a number of people.

    Our skeptical statisticians are only partially right, though, in thinking that there is nothing new under the sun. The problem of predicting an outcome given covariates is indeed old, and statisticians have had a deep understanding of this problem for a long time. Nonetheless, recent years have seen impressive new achievements for various prediction problems. This is true in the case of image recognition, where the covariates correspond to the pixels of an image file and the outcome might be the name of a person appearing in the image. This is also true for speech recognition, where the covariates correspond to the amplitudes in a sound file and the outcome is a written sentence. And this is true for the use of written text as data.

    How machines learn

    How do machine learning algorithms achieve their feats? Beyond the central ingredients of “big data” and computational power—both of which have advanced exponentially in recent years— most machine learning algorithms rely on two key ideas, regularization and tuning. And to go from prediction to causality, they furthermore rely on (randomized) experimentation. (For some technical lecture notes on the theory of machine learning, click here.)

    Regularization – automated skepticism

    Any association you observe between predictors and outcomes in a data set might be due to coincidence. This is a particularly important problem whenever you have many predictors to work with. With many predictors, the laws of probability dictate that in your data a fair number of predictors will be associated with the outcome by pure coincidence. If you were to assume that the same associations are going to hold for new data, you would get poor predictions. To avoid this problem, you regularize by discounting associations observed in the data to some extent, assuming for instance that the associations observed in the data are exaggerated.

    Tuning – how skeptical to be

    But how much regularization is optimal? Any machine learning algorithm has to try to answer this question in order to perform well. At this point tuning comes into play. In order to tune a prediction method, some “validation” data are initially put to the side. After training on the main data, the algorithm then tries to predict outcomes for these validation data, which it has not yet looked at. Tuning compares the predictions for the validation data to the actually observed outcomes. Based on the relationship between the two, the amount of regularization is chosen to get the best possible predictions for the validation data.

    Prediction, causation, and multi-armed bandits

    Being able to make accurate predictions is a good start, but by itself prediction does not solve anyone’s problem. Prediction only becomes useful when it translates into recommendations for actions—actions that serve whichever goals the algorithm’s designer might have, such as making you buy stuff or vote in the intended way. To figure out how to make you buy stuff, how to make you vote in the intended way, and so on, the machines need to go from correlation to causation, which requires another feature added to machine learning, namely experimentation—usually randomized experimentation.

    Any time you surf the Internet, many experiments are being performed on you. The content and design of websites are varied randomly to figure out which versions make you most likely to engage in the intended way. As the algorithms learn more about you and people like you, they adapt their behavior to get what they want. Such algorithms, which adapt their behavior over time, go by the colorful name of multi-armed bandit algorithms, in reference to their one-armed cousins living in Vegas. The idea is that you are a slot machine, and the algorithm is the calculating gambler. The algorithm tries out different arms to see which of them best achieves its goals. Over time, it focuses more and more on pulling the winning arms.

    Which masters do they serve?

    What are machine learning prediction methods used for? Suppose for a moment we had no idea. An educated guess would be that new technologies—including machine learning—will be more or less consistently to advance the objectives of the powers that be: Profit maximizing corporations competitively optimizing their interactions with consumers and workers; political parties seeking to win elections; the penal system making incarceration decisions; intelligence agencies seeking to identify targets of their operations, and so on. Such an educated guess would not go amiss.

    Profits

    Maybe the single largest application of machine learning methods to date is the targeting of advertisements. It is quite mind-boggling to consider: the entire business model of several corporations that are worth billions of dollars is to collect data on users in order to better choose which ads to show them. These companies are paid for each click on an advertisement, so they focus their efforts on displaying ads that have the highest probability of being clicked by each user.

    A related application, likely to expand a lot over the next few years, is differentiated pricing. Airlines already do it on a large scale, and many others will follow suit. The idea is to predict how sensitive a given individual is to prices in their purchasing decisions. Profit maximizing companies want to charge higher prices to less price-sensitive customers, and lower prices to more price-sensitive customers. What will happen as more data on individuals becomes available to companies, and prices become more differentiated? Standard economics predicts that corporate profits will go up, and that some individuals will face higher prices than before, while others will face lower prices. As we become more perfectly predictable, each of us will be charged the maximum amount that we are able and willing to pay for the products we purchase.

    A third corporate use of machine learning, somewhat more limited to date, is its use in hiring and promotion decisions. Job candidate CVs and past employee performance might be automatically processed to predict future performance, and to hire or fire accordingly.

    Lastly, banks and insurance providers have long relied on credit scores and risk assessments to set interest and insurance rates. These scores, used in innumerable aspects of American society, are effectively predictions of default risk, and they are becoming increasingly refined with new data and prediction methods.

    Votes

    Not only corporations leverage the new predictive capabilities; so do political parties. One of the key innovations that allowed the Obama campaign to win the White House in 2008 was that it was the first political campaign to systematically target its resources and efforts using statistical prediction methods. To maximize the chance of winning, this approach predicts which states are most likely to be pivotal, which voters in these states are most likely to switch their voting decision in response to which campaign messages, and which sympathetic individuals might be persuaded to vote rather than stay at home. The end result is that huge databases on voters are used to deliver individually tailored messages to a subset of potentially pivotal voters. Since the first Obama campaign, this approach has become widespread—used by both parties in the US, including in lower-profile races, and in other electoral democracies around the world.

    Law enforcement and militarism

    Predictive methods are also used in various ways by agencies of the state. Bail setting in US courts is based on an assessment by the judge of whether the defendant might commit a crime while awaiting trial. Various private companies now sell tools that provide such predictions to judges, using a host of information about defendants. These predictions, which have caused the largest controversies effectively determine whether defendants are incarcerated or free.

    Beyond the US border, intelligence agencies are involved in the most far-reaching mining of data, to identify suspects of terrorism. Among other things, the resulting predictions are used by the army and intelligence services to carry out targeted killings with drones—which have seen a massive expansion over the last decade.

    There is a thread that ties all these widely disparate applications of machine learning together: the use of data on individuals to treat different individuals differently. In part two, we will look at some of the effects such differentiated treatment.

  6. Copyright Humanism

    Comments Off on Copyright Humanism

    In 1989, after refusing to do so for over 100 years, the United States finally joined the Berne Convention, the leading international copyright treaty. By signing, the US transformed its copyright system from a formalities-laden, opt-in system of protection to a formalities-free, opt-out system of protection. In short, this transformation meant that copyright protections began automatically attaching to works at the moment of their creation, rather than after formal registration procedures had been completed.

    Then, in 1991, the Supreme Court’s decision in Feist clarified the contours of copyrightability under US copyright law. The Court noted that copyright “requires independent creation plus a modicum of creativity,” but explained that “the requisite level of creativity is extremely low; even a slight amount will suffice.” Even seemingly trivial and remarkably simple expressions receive copyright protections.

    Taken in tandem, these two developments yielded a copyright system under which, as copyright scholar Paul Goldstein put it, “the most casual expression—even a quickly scribbled shopping list—automatically gets copyright protection for the full copyright term.”1 Since this system arose, many commentators have lamented the implications of Berne and Feist, arguing that the current copyright regime is a poor fit for modern times—protecting too many works and works too trivial to merit protection.2

    This post adopts the unorthodox position that these developments in copyright law are, in fact, particularly well-suited for the digital age. An obvious impact of the internet is that for the first time in history most citizens became creators and publishers of “fixed expressions”: the subject matter of copyright. These user-created expressions are ubiquitous online: photos, videos, reviews, social media posts, websites, blogs, etc.—all of these count as fixed expressions. Moreover, these sorts of expressions that in a previous time may have indeed been quite trivial at scale are today increasingly valuable in the aggregate—both socially and economically.

    With these thoughts in mind, I argue for a refocusing of copyright theory and policy in light of the fact that copyrightable works created by individual users provide the valuable raw materials that power our information economy and pervade our digital landscape. When we take into account the immense importance of user-created expressions online, the chorus of criticisms that have labeled Feist and Berne as antiquated holdovers from a pre-internet age appears increasingly misguided.

    Berne’s Elimination of Formalities & America’s Initial Resistance

    The Berne Convention is the oldest international treaty that deals with the protection of copyrights, and, as Reagan noted upon America’s joining, it provides “the highest internationally recognized standards for the protection of works of authorship.” The Convention dates back to 1886 and is currently comprised of 176 signatory nations. But until 1989, the United States had refused to join the Convention as a Berne Union member.3

    The United States’ abstention from the Berne convention highlights the longstanding idiosyncrasies of the US copyright regime in relation to that of its international neighbors. Former Register of Copyrights Barbara Ringer4 wrote that US copyright policy’s historical “role in international copyright was marked by intellectual shortsightedness, political isolationism, and narrow economic self interest.” And, as professor Jane Ginsberg explains, the United States’ longstanding “non-membership in the Berne Convention was embarrassing […] because the US was the only non-Unionist Western Country.”

    One of the primary reasons for this discord centered on the issue of whether formalities should be a prerequisite for copyright protection. Formalities included, among other technicalities, requirements of notice in the form of the © symbol before publication; requirements of registration with the Copyright Office; and requirements of renewal of registration to enjoy a second period of copyright protection. During the mid-nineteenth century, “while in the US formalities were retained, in Europe, they were gradually softened and limited and in the end abolished altogether.”5

    There were a number of reasons that European governments had antipathy toward copyright formalities, including the following desires:

    1. To reduce the obstacles imposed on international trade in copyrighted works created by the hodgepodge of copyright formalities amongst various nations.6
    2. To promote the “anti-discrimination norm, introduced to avoid any kind of hidden disadvantages for foreign authors.”7
    3. To further the Berne Convention’s aspirational goals of creating a system of “universal international authors’ rights.”8

    Additionally, throughout this period, Europe saw the emergence of the personality theory of copyright take hold in debates over authorship rights. This theory conceived of a right “against any taking of the personal and unique form in which the author had expressed his thoughts or ideas.” Copyright scholar Stef van Gompel has traced the philosophical roots of this theory back to Immanuel Kant: “Kant believed that it is a man’s innate right to communicate his thoughts to the public. Therefore, authors should be vested with some right to control when, how, and by whom these thoughts, as expressed in their writings, are publicly disseminated.” It followed, for Kant, that “in parallel to a property right in the book as a physical object (‘ius in re’), authors have an innate right vested in their own person (‘ius personalissimum’).”9

    These philosophical ideas had influence on European lawmakers, and throughout the 19th Century the Berne Convention aimed to achieve “the eradication of superfluous and burdensome formalities or procedural barriers”10 to rights of authorship. Ultimately, the 1908 Berne Revision outlawed formalities altogether for member nations.

    Throughout late-19th Century Europe, “there was a growing consensus that the existence of copyright should not be subject to formalities and that failure to comply with formalities should never be the occasion of a loss of copyright.”11 By contrast, the United States continued to make “punctilious compliance with multiple statutory formalities a condition of both the existence and the enforcement of copyright.”12 This discord between the US and Europe continued for more than 80 years.

    A Growing American Aversion to Formalities

    As the 20th Century progressed, criticism of formalities began to emerge in the US as well. Much of this aversion emerged from experience. Failure to comply with US copyright law’s rigid procedures and arcane technicalities often yielded draconian punishments. A particularly harsh penalty was that failure to comply with technical formalities led to forfeiture of copyright. As professor John Kernochan has noted, the “sanction of forfeiture, in particular, is barbaric in its impact (i.e., it may wipe out the entire value of years of creative effort; it is disproportionate to any ends served and should be done away with).”13

    Even sophisticated entities with deep pockets and legal acumen were tripped up by the procedural maze of US copyright formalities. For example, the Harvard Law Review Association attempted to flex its copyright muscle against a free, open-source competitor to its Bluebook legal citation system. The Association soon discovered, however, that it had failed to re-register the 10th edition of its Bluebook, thereby forfeiting copyright interests in that edition and potentially substantial portions of subsequent editions.14 Another entity burdened by copyright’s byzantine formalities system was the Academy of Motion Picture Arts and Sciences, which, in 1989, faced an adverse district court decision holding that the iconic Oscar statuette was not entitled to copyright protection. The ruling found that the statue had entered the public domain because it did not itself bear a copyright notice—i.e. “©”—on it from 1929 through 1941.15

    But such formalities proved especially “burdensome and costly” for individual authors and creators—particularly the legally unsophisticated or inexperienced individual.16 Owing to the penalties of these burdens, the notion began to emerge that there was something “unfair that the individual authors may lose protection because of mere ignorance, innocent mistakes or careless failure to complete formalities.”17

    Thus, the US formalities-laden copyright system proved inequitable. Throughout the nineteenth-century, US copyright law predicated copyright protection on punctilious compliance with arcane legal formalities. As with other realms of the law, when compared to lawyered-up repeat players, legally inexperienced individuals faced an exceptionally uneven playing field: under the United States’ pre-Berne copyright regime, sophisticated corporate entities had a clear, nearly burden-free advantage on the creative class of individual, under-resourced copyright creators.

    As the 20th Century drew to a close, America’s longstanding opposition to the international community’s abolition of copyright formalities began to soften.

    The US Implements Berne: The Age of Instant Authorship

    In response to these developments, many copyright scholars and commentators began to champion the abolition of copyright formalities in the US. In 1988, Congress unanimously approved the Berne Convention Implementation Act, meaning that qualifying works would receive copyright protections instantly from the moment of their creation. The result was a radical expansion of the number of copyrighted works.

    As the world began transitioning into the digital age, “copyright formalities had been abolished in practically all countries” around the globe.18 And the US had finally joined the international community in providing copyright protections automatically to a work from the moment of its creation, ushering in the age of instant authorship.

    Feist‘s Modicum of Creativity Standard

    In 1991, three years after the US finally signed onto the Berne Convention, the Supreme Court “engaged in a fundamental re-examination and reformulation of the concept of originality applicable to all works of authorship.”19

    Dating back to 1903, the Supreme Court had articulated that copyright includes “all forms of writing, printing, engravings, etchings, etc., by which the ideas in the mind of the author are given visible expression.” The current Copyright Act echoes this broad subject matter of copyright: “Copyright protection subsists […] in original works of authorship fixed in any tangible medium of expression […] now known or later developed, from which they can be perceived, reproduced, or otherwise communicated.”

    In Feist the Court further clarified the contours of copyrightability under US law. The case involved two phonebook companies who litigated over one company’s copying the names and phone numbers from the other company’s phonebook. The copyrightability of the phonebook itself was conceded, leaving the discrete, disputed question over the copyrightability of the purely factual collection of names and phone numbers itself. Although the Supreme Court held that there was no copyright in the purely factual compilation, the Court clarified the extremely liberal and permissive nature of copyrightability: “[T]he requisite level of creativity is extremely low; even a slight amount will suffice.”

    The Court went on to note the ease with which most works meet this permissive standard: “The vast majority of works make the grade quite easily, as they possess some creative spark, no matter how ‘crude, humble, or obvious’ it might be.” Creativity, thus, “as a term of art in copyright law […] is pegged at the lower end, if not the bottom, of the spectrum of its wide-ranging common usage.”20

    Thus, Feist both defined the contours of the contemporary standard of copyrightability clearly and handily dismissed several misconceptions about copyrightability. Copyrightability does “not include requirements of novelty, ingenuity or esthetic merit.”21 Nor does it, as Robert Kasunic notes, require “contributions of time and effort” or labor. Feist decisively disavowed such considerations as irrelevant to questions of copyrightability. The Supreme Court explicitly dismissed the sweat-of-the-brow theory of copyright, embraced by several lower courts, which had considered investments of time and effort in determinations of copyrightability.

    The takeaway from Feist is that the standard for copyrightability is extremely permissive. Any expression of the mind that is fixed in a tangible medium receives copyright protections provided that it meets two requirements: 1) that it is original (“in the sense that it’s not copied”)22 & 2) that it displays a modicum of creativity. And—because of Berne—those copyright protections attach automatically at the moment of creation.

    Criticism of Feist & Berne in the Digital Age

    By the turn of the 21st century, many scholars began criticizing the tandem effect of Feist and Berne. Berne had made copyright an opt-out system under which works received copyright from the moment of their creation, thereby radically expanding the number of protected works. And Feist had set the standard of creativity so low that even the most trivial expressions qualified for copyright.

    The resulting criticism centered both on the lack of formality requirements and the trivial nature of works protected. In a paradigmatic example, Lawrence Lessig lamented in 2001 that: “There is no registration requirement—every creative act reduced to a tangible medium is now subject to copyright protection. Your email to your child or your child’s finger painting: both are automatically protected.”23

    The chorus of criticism has remained robust.24 Following criticisms like Lessig’s, scholars and commentators have argued variously that copyright is overprotective and that instant authorship is an antiquated holdover of the pre-internet age. Pamela Samuelson identifies the problem as being one of volume: there are simply too many copyrights. She writes, “virtually all of the photographs on Flickr, videos on YouTube, and postings in the blogosphere, as well as routine business memos and email messages, are original works of authorship that qualify for copyright protection automatically by operation of the law.”

    A Defense of Feist, Berne, and Copyright in the Internet Age

    The advent of the internet has revolutionized nearly every corner of American life, and copyright law is certainly no exception. An often-overlooked consequence of the internet is that for the first time in history most Americans are now regular creators and publishers of works of legal authorship. Each day ordinary citizens create copyrighted works and publish them for public consumption, contributing countless works to the digital landscape. User-created expressions permeate the internet in the form of photos, videos, reviews, social media posts, blogs, websites, and so on. Technology has allowed for a vast democratization of authorship. More people are creating and contributing more works to society than ever before.

    Despite these developments, discussions of copyright theory and policy have largely ignored how this explosion of expression and the democratization of authorship interacts with copyright law.

    Most people do not think of themselves as copyright authors, and scholars continue to treat copyright as a tool purely benefitting industry players. Indeed, copyright is often assumed to be and spoken of as contrary to the public’s interest. (For an example of this discourse, see James Boyle’s analogy to the enclosure movements: “The old limits to intellectual property rights—the antierosion walls around the public domain—are also under attack.”)

    Yet the scholarly discourse gives insufficient attention to the fact that most people in 21st Century America are not just consuming copyrighted works, but are themselves copyright content creators. At best, these scholars only acknowledge the public as copyright creators to dismiss them as creators of trivial works, undeserving of copyright protections.

    In thinking about the state and nature of criticisms of our copyright regime, it’s worth pausing to ask why the radical democratization of authorship should not be accompanied by an expansion in the number of people and percentage of the public holding intellectual property interests. As both the number and importance of individual copyright creators continues to grow, it is worth questioning the wisdom of any proposal to return to some form of arcane legal formalities that have historically disadvantaged the individual creator. We can consider copyright proponent Victor Hugo’s words on the subject: “Literary property is in the public interest. All the old monarchic laws have rejected, and continue to reject literary property. To what end? In order to enslave. The writer who is an owner [of his literary property] is a writer who is free.”25

    Our context has changed: While seemingly trivial in many cases, user-created works—the lifeblood flowing through the veins of the internet—are extremely valuable in the aggregate.

    User-created works make possible and valuable the world’s most successful and significant internet services, such as Google, Facebook, Twitter, YouTube, LinkedIn, and so on. All of these web 2.0 companies are built upon users’ contributions of their creative and expressive works. For example, in 2013, “people uploaded 350 million images to Facebook each day.” Regardless of the perceived triviality of many of those photos, in aggregate these images are both socially and economically significant, comprising the invaluable raw materials of one of the most powerful companies in the world. And in other businesses, not built around sharing and publishing, user-created content serves as the data inputs necessary for algorithms to perform particular tasks, the results of which are aggregated into salable products.26

    The wealth generated from this activity flows to those who control and aggregate its products, rather than, as Jaron Lanier puts it, “those who provide the ‘raw materials.'”27 What should be a fundamental insight into the role of user-generated content on the internet is all but ignored in current debates surrounding copyright, which prefer to treat individual user contributions as insignificant, rather than essential to the internet and the digital economy.

    To undo the developments of Feist and Berne—as copyright critics implicitly advocate—would disenfranchise the individual citizen of their intellectual property rights and would shrink the percentage of intellectual property owners, despite their significant contributions to the digital economy.

    Conclusion

    The impulse to discredit seemingly trivial and unsophisticated expressions as unworthy of copyright protection is myopic given the increasing importance such creative contributions have to society, the economy and individual expression.

    Indeed, I argue, the permissive, liberal copyright regime established by Berne and Feist is particularly well-suited to promote humanistic ideals and individual dignity in the digital age. Such a legal regime is well suited to govern a society in which most citizens are copyright creators, in which the individual copyright creator has become unprecedentedly important, and in which authorship has been radically democratized across society.

    Current debates about copyright theory and policy should account for the fact that in 2019, ordinary citizens are creating and contributing countless copyrighted works to the digital landscape every day. That development supports a copyright regime that empowers everyday citizens with property rights in their creations and frees those property rights from the barriers of arcane legal formalities.

    In the digital age, it is worth considering that a copyright regime that has expanded authorship rights dramatically might just be a good thing.

    Contemporary debates about social policy often express unease with the potential for mass inequality posed by the rapid extension of technology throughout society. Copyright law did not develop to intentionally address these concerns, but we can see how it could be well situated to help address them. Digital copyrights are naturally well-distributed, economically important property interests, but remain under-appreciated, underutilized, and under-monetized by common producers.

    As attention is starting to be paid towards issues such as data ownership, data privacy, and inequality in the digital age, existing copyright doctrine might provide an avenue to advancing the aims of digital equity. Although the digital age is nascent and the precise institutions to permit everyday individuals to capitalize on their intellectual property are lacking, Berne and Feist are the essential predicates to a more fundamentally fair copyright system that benefits everyday individuals.


    1. Goldstein, Paul. Copyrights Highway: From Gutenberg to the Celestial Jukebox. Stanford, CA: Stanford Law and Politics, 2003, 13.  ↩
    2. See, for example: Pamela Samuelson’s “Too Many Copyrights,” advocating for the reinstitution of formalities to “help address the problems related to too many copyrights”); Christopher Sprigman’s “Reform(aliz)ing Copyright,” arguing for “‘reformalizing’ copyright—i.e., for moving copyright back to a conditional regime”); Pamela Samuelson’s “Preliminary Thoughts on Copyright Reform,” suggesting that “copyright formalities may have a useful role in reshaping copyright norms and practices in the more complex world that has evolved in recent years”; Shlomit Yanisky-Ravid & Luis A. Velez- Hernandez’s “Copyrightability of Artworks Produced by Creative Robots and Originality: The Formality-Objective Model,” proposing “that courts ought to adopt a higher, more formal standard.” ↩
    3. Hatch, Orrin G. (1989) “Better Late Than Never: Implementation of the 1886 Berne Convention,” Cornell International Law Journal: Vol. 22 : No. 2 , Article 1.  ↩
    4. Barbara Ringer is a remarkable figure in the history of U.S. Copyright law. She was the first woman to serve as Register of Copyright, a position that she secured only after successfully suing for sex discrimination after having been improperly passed over for the job. She was also the lead architect of the Copyright Act, succeeded in codifying fair-use in statute, and advocated for making the Copyright Act among the first pieces of federal legislation to include dual gender pronouns. For an overview of her legacy, see this 2014 article by Amanda Levendowski. ↩
    5. Gompel, Stef Van. Formalities in Copyright Law: An Analysis of Their History, Rationales and Possible Future. Alphen Aan Den Rijn: Kluwer Law International, 2011, 89. ↩
    6. See: Samuelson, “Too Many Copyrights,” at 30: “One of the goals of the Berne Union was to overcome obstacles to international trade in copyrighted works such as burdens of complying with multiple formalities.” ↩
    7. De Rosnay, Melanie Dulong, and Juan Carlos De Martin, editors. The Digital Public Domain: Foundations for an Open Culture. 1st ed., vol. 2, Open Book Publishers, at *25-26. ↩
    8. Ginsburg, Jane C., “Berne-Forbidden Formalities and Mass Digitization” (April 28, 2016). Boston University Law Review, Vol. 96. For a discussion of Victor Hugo’s role at the Literary Congress of 1878 in promoting the notion of author’s rights, see Deven Desai’s “The Life and Death of Copyright” (August 28, 2012). Wisconsin Law Review, Vol. 2011, No. 2, 2011. ↩
    9. Gompel: “Les Formalités Sont Mortes, Vive Les Formalités! Copyright Formalities and the Reasons for Their Decline in Nineteenth Century Europe“, in: Privilege and Property: Essays on the History of Copyright, R. Deazley, M. Kretschmer & L. Bently, eds., p. 157, Cambridge: Open Book Publishers, 2010. ↩
    10. Hatch: “Better Late Than Never: Implementation of the 1886 Berne Convention”  ↩
    11. Gompel: Formalities in Copyright Law: An Analysis of Their History, Rationales and Possible Future, 100.  ↩
    12. Ginsburg: “Berne-Forbidden Formalities and Mass Digitization” ↩
    13. Comments of John M. Kernochan (1986), reprinted in Final Report of the Ad Hoc Working Group on U.S. Adherence to the Berne Convention, 10 COLUM.-VLA J.L. & ARTS 513 app. B at 685, 689 (1986). ↩
    14. For a discussion of the fascinating legal saga surrounding the Bluebook, see e.g. Leung, Peter: “Is Copyright an Obstacle to Properly Cited Justice?” ↩
    15. The Academy ultimately successfully appealed that decision. See: Academy of Motion Picture Arts & Scis. v. Creative House Promotions, Inc., 944 F.2d 1446, 1452 (9th Cir. 1991). ↩
    16. In “What Contracts Cannot Do: The Limits of Private Ordering in Facilitating a Creative Commons,” Niva Elkin-Koren notes that formalities “could actually discriminate against individual creators who are unable to carry the burden of legal counseling and registration.” For more on this, see Julia D. Mahoney, “Lawrence Lessig’s Dystopian Vision,” where she argues “all formalities impose burdens, and that those burdens are experienced most keenly by the inexperienced and uneducated.” ↩
    17. Gompel: Formalities in Copyright Law: An Analysis of Their History, Rationales and Possible Future, 10.  ↩
    18. Ibid, 2.  ↩
    19. Howard B. Abrams, “Originality and Creativity in Copyright Law,” 55 Law & Contemporary Problems, 5 (1992). ↩
    20. Ibid, 17.  ↩
    21. H.R. REP. NO. 94-1476, at 51 (1976) ↩
    22. Birdy, Annemarie. “The Evolution of Authorship: Work Made By Code,” 39 Columbia. Journal of Law & Arts 395, 2016, 398. ↩
    23. Lessig, Lawrence. The Future of Ideas: The Fate of the Commons in a Connected World. New York: Random House, 2003. ↩
    24. See e.g. Jane C. Ginsburg, “With Untired Spirits and Formal Constancy: Berne Compatibility of Formal Declaratory Measures to Enhance Copyright Title- Searching,” 28 Berkeley Tech. L. J. 1583, 1584 (2013) (“Formalities are back in fashion […] formalities’ confiscatory consequences, once perceived as barbaric,’ are to be celebrated.”); Jane C. Ginsberg, “The US Experience with Copyright Formalities,” Columbia Journal of Law and the Arts, vol. 33 No. IV (2010) (discussing the beneficial, information-providing role of formalities); Lawrence Lessig, Free Culture: How Big Media Uses Technology and the Law to Lock Down Culture and Control Creativity, New York: Penguin Press, 2004, pp. 287-90; Lawrence Lessig, Remix: Making Art and Commerce Thrive in the Hybrid Economy, New York: Penguin Press, 2008, pp. 260-65; William M. Landes and Richard A. Posner, “Indefinitely Renewable Copyright,” University of Chicago Law Review, 70 (2003), 471-518; Cecil C. Kuhne III, “The Steadily Shrinking Public Domain: Inefficiencies of Existing Copyright Law in the Modern Technology Age,” Loyola Law Review, 50 (2004), 549-563; Kevin A. Goldman, “Limited Times: Rethinking the Bounds of Copyright Protection,”University of Pennsylvania Law Review, 154 (2006), 705-740; and Pamela Samuelson, “Preliminary Thoughts on Copyright Reform,” Utah Law Review (2007), no. 3, 551-71. ↩
    25. Hugo, Victor. Société des Gens de Lettres de France (1897: 106). In: Jane C. Ginsburg, “From Hypatia to Victor Hugo to Larry and Sergey: ‘All the world’s knowledge’ and universal authors’ rights,” British Academy Law Lecture, 2012.  ↩
    26. Lanier, Jaron. Who Owns the Future? New York: Simon & Schuster, 2013. (“A multitude of examples of translations made by real human translators are gathered over the Internet. These are correlated with the example you send for translation. It will almost always turn out that multiple previous translations by real human translators had to contend with similar passages, so a collage of those previous translations will yield a usable result.”); Lanier, You Are Not a Gadget New York: Alfred A. Knopf, 2010. (“Instead of people being treated as the sources of their creativity, commercial aggregation and abstraction sites presented anonymized fragments of creativity as products that might have fallen from the sky or been dug up from the ground, obscuring the true sources.”) ↩
    27. Lanier, Jaron. Who Owns the Future? New York: Simon & Schuster, 2013, at page 8. ↩
  7. Experiments for Policy Choice

    Comments Off on Experiments for Policy Choice

    Randomized experiments have taken the fields of policy evaluation and empirical economics by storm. Hailed by their adherents as bringing about a new era of “evidence-based policymaking,” and a “credibility revolution” in economics and related fields, they have changed the world of policy research for good.

    The standard way of doing experiments

    In their simplest and most common form, randomized experiments work as follows. Suppose you are interested in a policy that is administered on an individual level, such as some training program, cash transfer, or health intervention. Your randomized experiment to test this policy would run like this: You first find a sample of individuals, where the sample is hopefully representative of the population of interest. Then you randomly select half of the individuals in this sample to be in the treatment group, and the other half to be in the control group. The policy is administered, and after the experiment you collect data on outcomes of interest—employment, for example. The policy is then declared a success if (1) the average employment in the treated group is higher than the average employment in the control group, and (2) the difference is “statistically significant.”

    But is this the best way to go about things? Can we maybe make better policy choices, with smaller experimental budgets, by doing things a little differently? This is the question that Anja Sautmann and I address in our new paper on “Adaptive experiments for policy choice.” A preliminary draft of this work is available here.

    The goal of many experiments is policy choice

    The ultimate goal of many experiments is to gather information to inform a policy choice. For example, we are currently evaluating a variety of interventions—providing information sessions, psychological counseling, or financial support—to help Syrian refugees in Jordan find jobs in the formal labor market.1 The goal of this project—like the goal of many experiments in policy, medicine, or business—is to understand which of these interventions is the most helpful.

    Trying to identify the best policy is different from estimating the precise impact of every individual policy: as long as we can identify the best policy, we do not care about the precise impacts of inferior policies. Yet, despite this, most experiments follow protocols that are designed to figure out the impact of every policy, even the obviously inferior ones.

    If we wanted to understand the impact of all potential treatments, the best thing to do would be to split participants equally across these groups. This is what traditional experimental design recommends, because it gives each treatment enough statistical power to identify a precise effect. However, suppose, in the context of our experiment on finding jobs for refugees, that providing information is an ineffective policy. In this case, splitting the sample at the outset will lead us to “waste” sample size learning about the precise impacts of a treatment that is clearly suboptimal: we would have preferred to put more effort into running a horse race between the other policies, providing counseling vs. providing financial resources.

    A better design for policy choice

    In our paper, we propose a framework that does a better job of identifying the best policy. The key to our proposal is staging: rather than running the experiment all at once, we propose that researchers start by running a first round of the experiment with a smaller number of participants. Based on this first round, you will be able to identify which treatments are clearly not likely to be the best. You can then go on to run another round of the experiment where you focus attention on those treatments that performed well in the first round. This way you will end up with a lot more observations to distinguish between the best performing treatments. And if you can run the experiment in several rounds, you can do even better.

    We show (both theoretically and in applications) that such a procedure, where you shift towards better treatments with the right speed, gives you a much better chance of picking the best policy after the experiment – which is what your goal was, after all. In contrast to the traditional method, ours allows you to achieve better outcomes with smaller sample sizes.

    Bandits—related, but different.

    Some readers might be reminded of so-called bandit problems and corresponding algorithms when reading this. Bandit algorithms are related, but different from what we are aiming for here. Bandit algorithms are often used for targeted advertising by the big internet corporations. They are based on continuous experimentation, where the goal is to maximize outcomes during the experiment itself. This is different from our goal, which is to pick the best policy after the experiment. (See this app, which allows you to calculate treatment assignment probabilities in this way.)

    The difference matters. Consider again the approach outlined above, where you run the experiment in two rounds. If you have a bandit objective, you will assign all participants in the second round to the one treatment that performed best in the first round. This maximizes your overall outcomes during the experiment, in expectation. But it does not maximize your chance of picking the best policy after the experiment. It does not allow you to continue learning about the runner-ups for the best policy. It would for instance be strictly better if you split the second round of the experiment equally between the two best performing treatments from the first round.

    To summarize, when we set out running experiments (as more generally in life), it is a good idea to take a moment and think about what our ultimate goal is. Since the goal of many experimenters is—at least implicitly—to aid policy choice, we should design experiments accordingly. The procedure that Anja Sautmann and I have proposed helps us do that, by adapting over time and focusing attention on the best performing alternatives.


    1. Co-authors on this project are Stefano Caria, Grant Gordon, Simon Quinn and Alex Teytelboym. The trial is pre-registered here. ↩
  8. The Emerging Monopsony Consensus

    Comments Off on The Emerging Monopsony Consensus

    Early on in The Wealth of Nations, Adam Smith asked who had the edge in negotiations between bosses and wage laborers. His answer: the bosses. In the case of a stalemate, landlords and manufacturers “could generally live a year or two” on their accumulated wealth, while among workers, “few could subsist a month, and scarce any a year, without employment.” Thus, concluded Smith in 1776, “masters must generally have the advantage.”

    As economic thought progressed over subsequent centuries, however, Smith’s view of labor markets gave way to the reassuring image of perfect competition. Provided there exists a large number of employers and a flexible labor force, competition for workers should push wages to their upper limit. In the view that undergirds labor econ 101, the healthy interplay of supply and demand erases the general advantage Smith ascribed to bosses.

    In recent years, a model more in line with Smith’s intuitions has grown to challenge the neoclassical ideal. Under the banner of monopsony, economists have built up an impressive catalog of empirical work that offers a more plausible baseline model for labor markets. Once more of a niche subfield, monopsony now attracts practitioners from a wide range of economics departments. President Obama’s Council of Economic Advisers devoted an entire policy report to monopsony research.

    The theory of monopsony has a long history; what’s novel in recent research is the use of big data to measure it at a national scale. To take a notable recent example, Kevin Rinz, a researcher at the U.S. Census Bureau, found that as employers grow larger and more concentrated—a classic indicator of monopsony power—wages suffer. Using internal Census data, Rinz estimated that a local increase in employer concentration from the median up to the 75th percentile is associated with a 10 percent drop in workers’ wages.

    The reasoning behind the monopsony model is straightforward. Rather than starting from a mental picture of innumerable identical employers battling for a pool of workers, monopsony imagines an extreme case of just one major employer. Think of an Iron Belt company town or an Appalachian coal mine. Absent organized labor, the firm will push wages below what would obtain in a competitive market, where underpaid workers can always seek greener pastures at other employers. Just as monopolies push prices up, monopsonies keep wages low.

    For most workers, of course, the contemporary labor market does not resemble a company town. But the crucial point is the assumption of wage-setting power. Presuming that firms have at least some power to set wages, monopsony theorists argue, provides a more fruitful approximation of reality than the competitive model, in which individual firms pay only what the market dictates.

    This shift in perspective has major ramifications. The monopsony model predicts, for instance, that minimum wage increases will lead to few, if any, job losses—a pattern observed in numerous minimum wage studies—as long as markets deviate from perfect competition. In short, competitive models presume each worker is paid very close to the value of what they produce for the employer, so that any externally imposed wage bump will make it uneconomical to employ so many workers, leading to layoffs. In contrast, the monopsony model assumes a wedge between what employees produce and what they are paid, so that a modest minimum wage hike may cut into profits, but won’t put businesses in the red.

    The new studies into monopsony power test the prediction that the fewer employers there are in an industry, the lower the wages will be. To do so, researchers have drawn from vast data sets covering wide swaths of the American workforce. Although their methods vary, these studies arrive at a similar conclusion: As labor markets become more concentrated, paychecks take a hit—particularly for those at the bottom of the pay ladder.

    In the Rinz working paper, data pulled from millions of Census filings produce a nuanced picture of the U.S. workforce. Beyond finding a correlation between bigger employers and smaller paychecks at the local level, Rinz describes how monopsony power increases inequality between those at the top of the income ladder and those at the bottom—particularly older workers, white men, and those with a high school diploma or less.

    It might be tempting to apply these findings to the generational rise in American income inequality. But Rinz cautions against this. A counter-intuitive fact about the U.S. business landscape is that since the late 1970s, industrial concentration has fallen locally even as it has risen nationally. As other researchers have confirmed, the decades-long consolidation of industry into fewer and fewer hands might hold nationwide, but not necessarily for individual communities. (Only in the last 15 years have a majority of localities seen rising concentration).

    Average employer concentration at the local level for the top four firms in every industry. HHI refers to the Herfindahl-Hirschman Index, which increases with higher levels of concentration. Source: Rinz (2018).

    Average employer concentration at the national level for the top four firms in every industry. HHI refers to the Herfindahl-Hirschman Index, which increases with higher levels of concentration. Source: Rinz (2018).

    This dynamic reflects the rise of chains. Pharmacies, for instance, were once mostly local affairs. But as CVS and Walgreens multiplied, localities that had only one or two employment options for pharmacists now had three or four. Even if the chains put a local pharmacy out of business, there would be more overall employment options (and often higher wages) for a pharmacist at the local level, while nationally the number of pharmacy companies declined. In short, Rinz argues, we can not blame rising inequality on growing local concentration among employers.

    Other recent investigations into monopsony have brought similar nuance. A working paper from Yue Qiu of Temple University and the University of Minnesota’s Aaron Sojourner used big data to confirm Rinz’s broader conclusions. Among their other findings: the wage effects of monopsony could be counteracted by unions, and increased employer concentration is associated with a lower probability of workers being covered by health insurance.

    These studies lend credence to a model that for generations has been taught, if at all, as a curious special case. A 2003 review of leading labor economics textbooks found that authors spent, on average, just 8 pages out of 500 discussing monopsony. But the breadth of the recent research suggests that monopsony is a ubiquitous force in American labor, not some rare oddity.

    There are other barriers to monopsony becoming an accepted theory of labor market dynamics. One common and oft-repeated misunderstanding: If dominant firms have monopsony power, why do we see larger, more profitable firms paying higher wages? Doesn’t monopsony theory predict lower wages among superstar firms like Apple and Google?

    Leave aside the fact that Silicon Valley recently provided an uncommonly overt example of firms actively colluding to hold down wages. The truth is, monopsony theory does not deny that industry leaders might pay their workers more. In the most fully developed monopsony model, formalized in Alan Manning’s 2003 Monopsony in Motion, super-productive firms should pay higher wages (even if a greater portion of an employee’s individual contribution goes to profits). The large-firm wage premium, insofar as it still exists, actually supports monopsony.

    Misapprehension of monopsony might stem in part from its name, supplied in 1932 by the pioneering Joan Robinson. Taken literally, it refers to a market with just one seller. In Manning’s theory of monopsony, however, the concept covers all the frictions and informational asymmetries present in labor markets. Wherever obstacles keep workers from easily switching jobs, or discovering outside job openings, or knowing what their coworkers make (a particular problem for women), the employer has an edge. The more edges a firm has, the more it can hold down wages.

    Note that nothing in the exposition above refers to the size of the firm. Being large helps, but it doesn’t guarantee wage-setting power. That’s why recent monopsony work has also focused on phenomena such as the broad expansion of employee non-compete agreements, which can prevent workers from seeking out better-paying opportunities. To the surprise of many, non-competes have been found to cover workers cross the spectrum, from highly trained scientists to Jimmy John’s sandwich makers.

    It remains difficult, however, to consolidate the various potential contributors to monopsony power into a metric as tractable as employer size. Despite this limitation, research has been fairly consistent in pointing toward the existence of monopsony exploitation. A recent meta-analysis of 801 estimates across 38 published studies approximated that monopsony could create a wage markdown, or gap between real and potential wages, of up to 26.7 percent.

    It would be naive to presume employers have absolute power over wages. If workers had no sway, we wouldn’t see wages rise when unemployment falls suitably low. But it would be similarly naive to think employers lack any wage-setting power. As the monopsony model suggests, it is reasonable to begin from the assumption that employers do set wages. The question is how much.

    Again, what’s new here is the methodology, not the underlying ideas. As the patron saint of free-market economics wrote in 1776: “Masters are always and everywhere in a sort of tacit, but constant and uniform, combination, not to raise the wages of labour above their actual rate.” Today, at least, that idea has a name.

  9. Ideology in AP Economics

    Comments Off on Ideology in AP Economics

    Introduction

    When the media talks about ideological indoctrination in education, it is usually assumed to refer to liberal arts professors pushing their liberal agenda. Less discussed is the very different strain of ideology found in economics. The normative import is harder to spot here, as economics presents itself as a science: it provides an empirical study of the economy, the common wisdom might go, just as mechanical engineering provides an empirical study of certain physical structures. When economists offer advice on matters of policy, it’s taken to be normatively neutral expert testimony, on a par with the advice of engineers on bridge construction. However, tools from the philosophy of explanation, in particular the work of Alan Garfinkel, show how explanations that appear purely empirical can in fact carry significant normative assumptions.1 Using these tools, we can uncover the ideology embedded in economics.

    More specifically, we’ll look at the ideology embedded in the foundations of traditional economics—as found in a typical introductory micro-economics class. Economics as a whole is diverse and sprawling, such that no single ideology could possibly be attributed to the entire discipline, and many specialized fields avoid many of the criticisms I make here. Despite this, if there are ideological assumptions in standard introductory courses, this is of great significance.

    A huge number of people take introductory economics courses, including many people who become involved in high-level political decision making, and, for the most part, these students will have little interaction with more nuanced sub-fields. Including something in a standardized intro course effectively canonizes it, and policy makers who’ve taken such a course will generally be comfortable relying on its principles in decision making, except in the unlikely event that a relevant specialist is in the room at the time to point out their shortcomings. Bloomberg’s Noah Smith makes a similar point about the significance of introductory texts in relation to the deeply flawed theory of labor they offer.2

    To this end, we’ll use MIT’s EdEx guide to AP Microeconomics, taught by renowned economist John Gruber, as our foil: it is a high quality, easily accessible teaching resource that provides many students with their first exposure to economics (from hereon, I’ll simply call it ‘MIT Micro’).3 For the most part, this course makes a good faith effort to be even-handed and to demonstrate how different political viewpoints can be defended within the framework it sets up. This book is among the best of its kind, which allows me to make observations about embedded ideology of the discipline without indulging in cheap shots, as often happens when economics is criticized from the left. The point here is not to claim that economists are ideologues, but rather that certain ideological principles are deeply embedded in the subject matter, regardless of the intent of the person presenting it.

    Garfinkel’s View

    Though many economists view their discipline as an empirical science, they nevertheless believe it can be used to inform moral debate. This is hardly controversial, since facts about how economies function are bound to influence how a just economy should be regulated. As Gruber puts it in MIT Micro:

    [We can] use the tools of economics to address what are known as normative questions, such as is this a good thing or a bad thing? Normative questions have answers that are opinions… Even [so], the tools of economics can be very powerful to help inform these opinions.

    In keeping with this sentiment, Gruber is conscientious throughout the course about trying to distinguish a normative thesis proposed within an economic framework from an empirical economic discovery—unlike many economic pundits. Philosopher Alan Garfinkel, however, argues that even if the distinction between empirical and normative claims is scrupulously regimented, economic explanations can still distort the normative debate.

    Garfinkel’s general point is that explanations come with a contrast space: we don’t simply explain why something holds, instead we explain why something holds rather than some alternatives. For example, when answering questions about why the airline industry functions as it does, economics can explain why it is an oligopoly rather than perfectly competitive, but cannot explain why the airline industry uses jets rather than individual rocket packs—for this we’d have to turn to physics. The contrast space determines what explanations are apt answers to a given question.

    As Garfinkel observes, the contrast space one appeals to may have normative consequences. He uses the example of the robber Willie Sutton, who was asked by a priest why he robs banks: Sutton replied, “that’s where the money is.” Sutton’s response explains why he robs banks rather than bakeries or museums, but the fact that he’s robbing something is simply assumed—it is not part of the contrast space. This means that discussing whether robbery is right or wrong is not on the table. In general, in order to criticize something, one must be able to point to a better available alternative—if a condition is excluded from the contrast space, avoiding it is not nefarious or unjust, it’s just inevitable.

    A second way explanations influence normative debate comes from the kind of causal mechanisms they allow one to appeal to. Garfinkel uses the example of a student, Mary, getting a B in her final. One contrast space for explaining this would include alternative scenarios in which Mary gets A, or Mary gets C, while not considering factors external to Mary. In this case one could cite Mary’s work ethic, her ability to perform under pressure, or her teacher’s disposition towards her. Though these are empirical factors, they can be used to underpin ethical claims. If the explanation for Mary getting a B rather than an A is her questionable work ethic, then we will conclude that the grade is deserved. If the explanation, though, is that the teacher despises her, and grades her exceptionally harshly, then we will conclude that the grade is unfair.

    However, if we ask ‘why did Mary get an A on this exam?’ and consider in the contrast space not just features about Mary, but also features about the examination system, we may arrive at different conclusions. When contrasting the exam with other possibilities, we might note that the teacher is grading on a strict curve that only allows one student in the class to receive an A, or that the exam includes a huge number of questions and a tight time limit, rewarding speed rather than understanding. Pointing to one of these factors as an explanation for Mary’s grade could lead us to conclude that the result was unfair.

    What these examples are meant to illustrate is that, when explaining something, one can only appeal to causal factors that distinguish between alternatives in the contrast space—so if the contrast space is unaffected by events we consider morally objectionable, it prejudices the moral debate by excluding them from the discussion.

    Turning to economic explanations, Garfinkel criticizes the individualism of the explanatory framework. He sees the central question in economic justice as being ‘why is there this distribution of goods among individuals?’ If the factors providing an answer are without reproach, then it seems the current distribution is just, while if they bring up problems, we may conclude it is morally unacceptable.

    The contrast space is the set of different possible distributions of individual holdings; the question is why there is one distribution rather than another. Further, according to Garfinkel, the basic object of economic explanation is why any given individual holds a given share; one thus begins by explaining this for each individual in a society, and then conjoins all the individual explanations to provide an overall explanation of the total distribution of goods in society. Garfinkel’s primary target here is a libertarian conception of justice, which wants to look at the individual causal histories of each person’s acquisition of goods. On this view, if there is no injustice to be found in how a person acquired their holdings, then those holdings must be an acceptable part of a just society.4

    Garfinkel points out that this model of explanation is unacceptably restrictive. First, looking at individual’s holdings in isolation rules out identifying relative levels of wealth as a source of injustice. He uses the example of levels of weapon ownership: citizens may be concerned with a peer collecting a large stockpile of weapons, and the problem is not necessarily with them having 10 or 20 guns, with the number considered in isolation. The problem is with the shift in power dynamics brought about by a single person owning far more weapons than anyone else in the community. Analogously, holding a great deal more money than anyone else allows one to, for example, distort the political process undemocratically.

    Second, looking just at the causal histories of individual holdings in isolation prevents us from seeing the causes of structural features of wealth distribution. If, when asking “why are goods distributed this way?”, we worked with a contrast space that recognized structural features of the economy, our explanation might appeal to Piketty’s claim that Capital tends to accumulate at such a rate that those without inheritance stand little chance of earning their way into the upper classes, or Ta Nehisi Coates’ explanation of how systemic discrimination like redlining contributed to the contemporary racial wealth gap.5 These explanations might lead us to find injustice in the current system that would not be apparent if we restricted our attention to individualist explanations.

    Though Garfinkel’s criticisms are persuasive, they target the explanations of political philosophers of a certain era who draw upon economic considerations, rather than economic explanations themselves. Economists do not generally subscribe to the strict individualism defended by Robert Nozick, whose account is Garfinkel’s primary target. Indeed, many of the key elements of economic explanation—supply and demand, or the competitiveness of a market—are clearly structural in nature. Garfinkel’s insights do lead to a critique of general economic explanation, but this requires further investigation, specifically a look at economic conceptions of welfare.

    Economics and Welfare

    Economic models broach normative questions by employing the notion of utility. As MIT Micro puts it: “Utility is what we call happiness, or well-being… A utility function describes how happy the goods you consume make you. A utility function tells you how well off you are.” If this is intended as a complete definition of happiness, it is woefully inadequate. Whether you are happy clearly depends on much more than the goods you consume. It depends on the structure of society and your place within it, your friends and family, your health, and so on. I’m sure economists would readily admit this: they are not concerned with all aspects of happiness, only the economic component.

    However, even this qualification conceals an ambiguity. On the one hand are the aspects of happiness that can feasibly be measured and modeled within economics; on the other are those that are at least partially determined by the state of the economy. These notions are not equivalent: economic factors play a role in determining just about all aspects of human happiness, but many of these cannot be modeled within economics. To take one example, many economic factors play a role in perpetuating racial injustice, including lenient inheritance taxes, and patterns in home ownership and public-school funding that create de facto segregation.6 However, economics—at least within its traditional framework, as presented as foundational to every economics students—is not able to measure and model how being a member of an unjustly treated racial group affects happiness.7

    The relationship between economic models and normative concerns comes to the fore in the analysis of welfare. From MIT Micro: “Welfare economics is about the measurement of economic outcomes on well-being. It gives us the tools and metrics to compare alternative market outcomes.” We can get to the bottom of the constraints the economic conception of welfare places on policy debates by looking at Gruber’s framing of the debate on redistribution and equity:

    The economist’s solution to this [question of understanding social welfare] is to create a social welfare function, which is loosely speaking, a utility function for society as a whole… The classic social welfare function is the utilitarian social welfare function, in which the goal of society is to maximize the sum of individualities. Everyone’s utility is weighted the same, and this function just adds them all up.

    The classical welfare function ends up looking fairly liberal due to the diminishing marginal utility of money. Marginal utility refers to the amount of happiness getting one more dollar would give. Marginal utility diminishes the wealthier one gets—in that another dollar means less to someone with lots of money than it does to someone with very little. An extra 1000 dollars will, in general, change the life of a person on minimum wage with no savings much more than it will for someone who is extremely wealthy. Therefore, if the government takes ​1000 dollars from a wealthy person and gives it to a poor person, the utility of the poor person will increase much more than the wealthy person’s utility decreases: a tax system that redistributes resources from the rich to the poor will increase the total utility in a society.

    Despite this, economists tend to stop short of recommending redistribution to complete equality. Gruber, in MIT Micro, employs the metaphor of a leaky bucket to illustrate the idea that, under normal conditions, transferring wealth entails inefficiency:

    The benefit of redistribution is that resources that move from the rich, with their low marginal utility for these resources, to the poor, with their high marginal utility for these resources. Equity improves when the bucket carries resources from the rich to the poor. The cost of redistribution is the deadweight loss incurred when the tax and redistribution shrink the supply of labor.

    The crucial claim here is that redistributing wealth shrinks the labor supply: “if the government taxes wages, it lowers the return to work by reducing the opportunity cost of leisure.” As Gruber later notes, this only occurs if the method of redistribution reduces the effective wage for each hour of labor, as would occur with a credit that brings annual income up to some floor (but offers nothing to those earning above the floor). It does not apply to earned income tax credits or universal basic income. Indeed, earned income tax credits should increase the labor supply for those earning it, and given diminishing marginal utility, this should outweigh the reduced incentive to work for the high earners being taxed.

    The permissible options for addressing inequality, as ‘informed by economics’, are severely limited. According to MIT Micro, “the decision of whether and how much to redistribute comes down to two things—how leaky the bucket is and how much of a leak society is willing to put up with.” In elaborating, Gruber recognizes a conservative viewpoint which resists redistribution on moral principle—not just because of an aversion to inefficiency. This position has been made sufficiently precise within the economic framework that, for Gruber, is fit for normative debate: according to this view, wealthy people have worked hard and deserve their greater income, no matter the reduced overall utility this entails:

    It’s probably important to redistribute enough wealth so that people won’t starve or die of the flu, but once we’ve met some basic standard, why should I tax you more if you decide to work 18 hours a day at a fancy bank to make a lot of money?

    On the grounds Gruber gives here, one could defend a system of only minimal redistribution to ensure no one falls into destitution, or even no redistribution at all. On the other hand, one could minimize the significance of such desert claims and defend a more liberal redistribution proposal, insofar as it maximizes total utility. One could go still further and argue for a kind of redistribution that satisfies Rawls’ difference principle (making the worst off as well off as possible), though whether there is a plausible defense of this principle available is questionable.8

    This may seem like a pretty broad spectrum of views to choose from, but it remains inadequate. The key fact is that when deciding on matters of redistribution, one’s conception of a just society must be limited within the contrast space provided by the economic model. This means that one must use a social welfare function that draws only upon utility in its crude economic sense. This welfare function encodes its own kind of individualism, not in terms of explaining how individuals acquired their wealth, but in the relationship between individuals’ wealth and their happiness. Though the empirical side of economic explanations allows for structural features, the normative side does not.

    When asking ‘why is there this distribution of goods?’, and looking for a justification rather than simply an empirical causal history, we will want to make reference to the level of welfare that comes with this distribution. Within the traditional economic framework, the contrast space only looks at the different possible levels of utility for different individuals, and different levels of wealth underlying them. Therefore, we are not able to appeal to structural features when answering this question.

    In economic explanations of this kind, we are not able to look at how the welfare of society is dependent on racial disparities in wealth, or differences in democratic power depending on levels of inequality.9 The problems that arise from this are two-fold: First, we are not able to judge economic systems based on how well they do with regard to these structural aspects of welfare; second, we are not able to look at the histories of the structural features when evaluating whether the current levels of social welfare are justified. If we were, we might identify that, for example, a history of racial exploitation produced certain structural aspects of welfare, and thus that our economic system is unjust.10

    Conclusion

    What is to be done? It would not necessarily be recommended that we revise the notions of utility and welfare to recognize all these structural factors, since that might well make tractable predictive models impossible. To be clear, the problem is not simply that economic models do not recognize all aspects of well-being, it’s that economic policy influences a whole range of factors relevant to well-being and injustice that are invisible to the discipline itself. Economists alone cannot determine what economic policies should be pursued. This should not be seen as a terrible problem for economics—after all, engineering research alone is not sufficient to decide whether it’s a good idea to build a particular bridge at a particular location (it can’t say whether such a bridge is affordable or needed). It does mean that economists should exercise humility in how to present their advice, and one would hope an introductory course in economics would emphasize this.

    A starting point for improvement would be to embrace and make explicit the normative commitments that economic models bring, since much of what is objectionable comes from ideology creeping into apparently value neutral models.11 Building on this, dialogue between economists and those in other areas concerned with aspects of justice affected by the economy is essential.12

    The aim must be a continuous back and forth, with those in other areas offering input on the broader consequences of economic outcomes, and economists coming back with the empirical predictions on what happens in attempts to meet these outside goals.

    It’s essential that these considerations are communicated to all economics students, no matter what level of expertise they reach. One should not subscribe to the individualist conception of welfare described above, without being aware of having made an ethical decision in doing so. And an introduction to economics is duty bound to make this clear.


    1. See Garfinkel, A. (1981). Forms of explanation. New Haven: Yale University Press. ↩
    2. https://www.bloomberg.com/view/articles/2018-04-05/supply-and-demand-does-a-poor-job-of-explaining-depressed-wages. ↩
    3. The course can be viewed for free here: https://courses.edx.org/courses/course-v1:MITx+14.01x+2T2017/course/ ↩
    4. The clearest defender of such a view is Robert Nozick in Anarchy, State, Utopia. ↩
    5. Piketty, T. (2014). Capital in the 21st Century; Coates, T. N. (2014). The case for reparations. The Atlantic, 313(5), 54-71. ↩
    6. For an exploration of aspects of this see https://www.vox.com/2016/6/6/11852640/cartoon-poor-neighborhoods ↩
    7. These are exactly the kinds of questions that sub-disciplines alluded to above-such as developmental economics-attempt to answer. My problem is that these fields are rendered invisible in traditional introductions to economics. ↩
    8. See Rawls, J. (2009). A theory of justice: Revised edition. Harvard university press. For criticism see, e.g., Harsanyi, J. C. (1975). Can the maximin principle serve as a basis for morality? A critique of John Rawls’s theory. American political science review, 69(2), 594-606. ↩
    9. This is an issue that has recently been pressed by Corey Robin – see e.g. https://www.nytimes.com/2018/08/24/opinion/sunday/what-socialism-looks-like-in-2018.html ↩
    10. A recent, stark structural feature in need of explanation is the difference in welfare between Puerto Rican Americans and mainlanders in the aftermath of 2017’s hurricanes. The economic explanation of this, focusing not on the immediate response, but the longer-term differences in infrastructure investment, are likely to reveal much injustice. See, e.g, https://www.vox.com/2017/9/25/16361310/hurricane-maria-puerto-rico ↩
    11. This is in line with Anthony Atkinson’s argument for a return to welfare economics – see http://citeseerx.ist.psu.edu/viewdoc/download?doi=10.1.1.364.5383&rep=rep1&type=pdf ↩
    12. A promising development here is Michael Porter’s ‘Social Progress Index’ aiming to offer an alternative to GDP that better tracks happiness. See https://qz.com/678910/harvard-researchers-have-isolated-a-key-to-happiness-and-iceland-is-helping-them-test-it/ ↩